Resource
| Id | TF_ChIP-seq/ENCSR000BJX |
|---|---|
| Type | position_score |
| Version | 0 |
| Summary | TF_ChIP-seq ENCSR000BJX [biosample_summary="Homo sapiens HepG2" and target="SP1"] |
| Description |
status: released biological_replicates: Rep 1, Rep 2 summary: output_type: IDR thresholded peaks audit_internal_action: Released analysis {ENCAN029VQS|/analyses/ENCAN029VQS/} has in progress subobject document {1c22705b-d200-491d-ae6e-fa64bb049aa9|/documents/1c22705b-d200-491d-ae6e-fa64bb049aa9/} audit_internal_action: Released analysis {ENCAN029VQS|/analyses/ENCAN029VQS/} has in progress subobject quality standard {encode4-tf-chip|/quality-standards/encode4-tf-chip/} audit_not_compliant: Replicate concordance in ChIP-seq experiments is measured by calculating IDR values (Irreproducible Discovery Rate). ENCODE processed IDR thresholded peaks files {ENCFF806TIM|/files/ENCFF806TIM/} processed by ChIP-seq ENCODE4 v1.6.1 GRCh38 pipeline have a rescue ratio of 11.84 and a self consistency ratio of 86.47. According to ENCODE standards, having both rescue ratio and self consistency ratio values < 2 is recommended, but having only one of the ratio values < 2 is acceptable. audit_warning: Processed alignments file {ENCFF718SND|/files/ENCFF718SND/} processed by ChIP-seq ENCODE4 v1.6.1 GRCh38 pipeline has 17793239 usable fragments. The minimum ENCODE standard for each replicate in a ChIP-seq experiment targeting SP1-human and investigated as a transcription factor is 10 million usable fragments. The recommended value is > 20 million, but > 10 million is acceptable. (See {ENCODE ChIP-seq data standards|/data-standards/chip-seq/} ) audit_warning: Processed alignments file {ENCFF241ZKB|/files/ENCFF241ZKB/} processed by ChIP-seq ENCODE4 v1.6.1 GRCh38 pipeline has 12139668 usable fragments. The minimum ENCODE standard for each replicate in a ChIP-seq experiment targeting SP1-human and investigated as a transcription factor is 10 million usable fragments. The recommended value is > 20 million, but > 10 million is acceptable. (See {ENCODE ChIP-seq data standards|/data-standards/chip-seq/} ) audit_warning: PBC1 (PCR Bottlenecking Coefficient 1, M1/M_distinct) is the ratio of the number of genomic locations where exactly one read maps uniquely (M1) to the number of genomic locations where some reads map (M_distinct). A PBC1 value in the range 0 - 0.5 is severe bottlenecking, 0.5 - 0.8 is moderate bottlenecking, 0.8 - 0.9 is mild bottlenecking, and > 0.9 is no bottlenecking. PBC1 value > 0.9 is recommended, but > 0.8 is acceptable. ENCODE processed alignments file {ENCFF241ZKB|/files/ENCFF241ZKB/} processed by ChIP-seq ENCODE4 v1.6.1 GRCh38 pipeline was generated from a library with PBC1 value of 0.89. audit_warning: PBC2 (PCR Bottlenecking Coefficient 2, M1/M2) is the ratio of the number of genomic locations where exactly one read maps uniquely (M1) to the number of genomic locations where two reads map uniquely (M2). A PBC2 value in the range 0 - 1 is severe bottlenecking, 1 - 3 is moderate bottlenecking, 3 - 10 is mild bottlenecking, > 10 is no bottlenecking. PBC2 value > 10 is recommended, but > 3 is acceptable. ENCODE processed alignments file {ENCFF241ZKB|/files/ENCFF241ZKB/} processed by ChIP-seq ENCODE4 v1.6.1 GRCh38 pipeline was generated from a library with PBC2 value of 8.68. |
| Labels |
|
Scores (1)
| ID | Type | Default annotation | Description | Histogram | Range | Summary |
|---|---|---|---|---|---|---|
| TF_ChIP-seq_ENCSR000BJX | float |
TF_ChIP-seq_ENCSR000BJX |
TF_ChIP-seq ENCSR000BJX [biosample_summary="Homo sapiens HepG2" and target="SP1"]
|
 |
[4.31, 337] |
|
n counts base pairs; sd is the population standard deviation.
Coverage
| Chromosome | Covered positions | Covered % | Segments |
|---|---|---|---|
| all chromosomes | 8214798 | 0.26% | 28506 |
| chr1 | 770228 | 0.31% | 2674 |
| chr2 | 753078 | 0.31% | 2635 |
| chr3 | 472930 | 0.24% | 1649 |
| chr4 | 281186 | 0.15% | 959 |
| chr5 | 340639 | 0.19% | 1165 |
| chr6 | 539829 | 0.32% | 1895 |
| chr7 | 378063 | 0.24% | 1295 |
| chr8 | 308094 | 0.21% | 1068 |
| chr9 | 331454 | 0.24% | 1130 |
| chr10 | 343614 | 0.26% | 1185 |
| chr11 | 367837 | 0.27% | 1272 |
| chr12 | 367125 | 0.28% | 1295 |
| chr13 | 166720 | 0.15% | 567 |
| chr14 | 312235 | 0.29% | 1082 |
| chr15 | 232502 | 0.23% | 793 |
| chr16 | 410118 | 0.45% | 1449 |
| chr17 | 506614 | 0.61% | 1769 |
| chr18 | 143825 | 0.18% | 506 |
| chr19 | 412133 | 0.70% | 1447 |
| chr20 | 342712 | 0.53% | 1200 |
| chr21 | 79570 | 0.17% | 282 |
| chr22 | 190848 | 0.38% | 645 |
| chrX | 160123 | 0.10% | 533 |
| chrY | 3321 | 0.01% | 11 |
| 3342 contigs with no values (129077085 bp) | 0 | 0.00% | 0 |
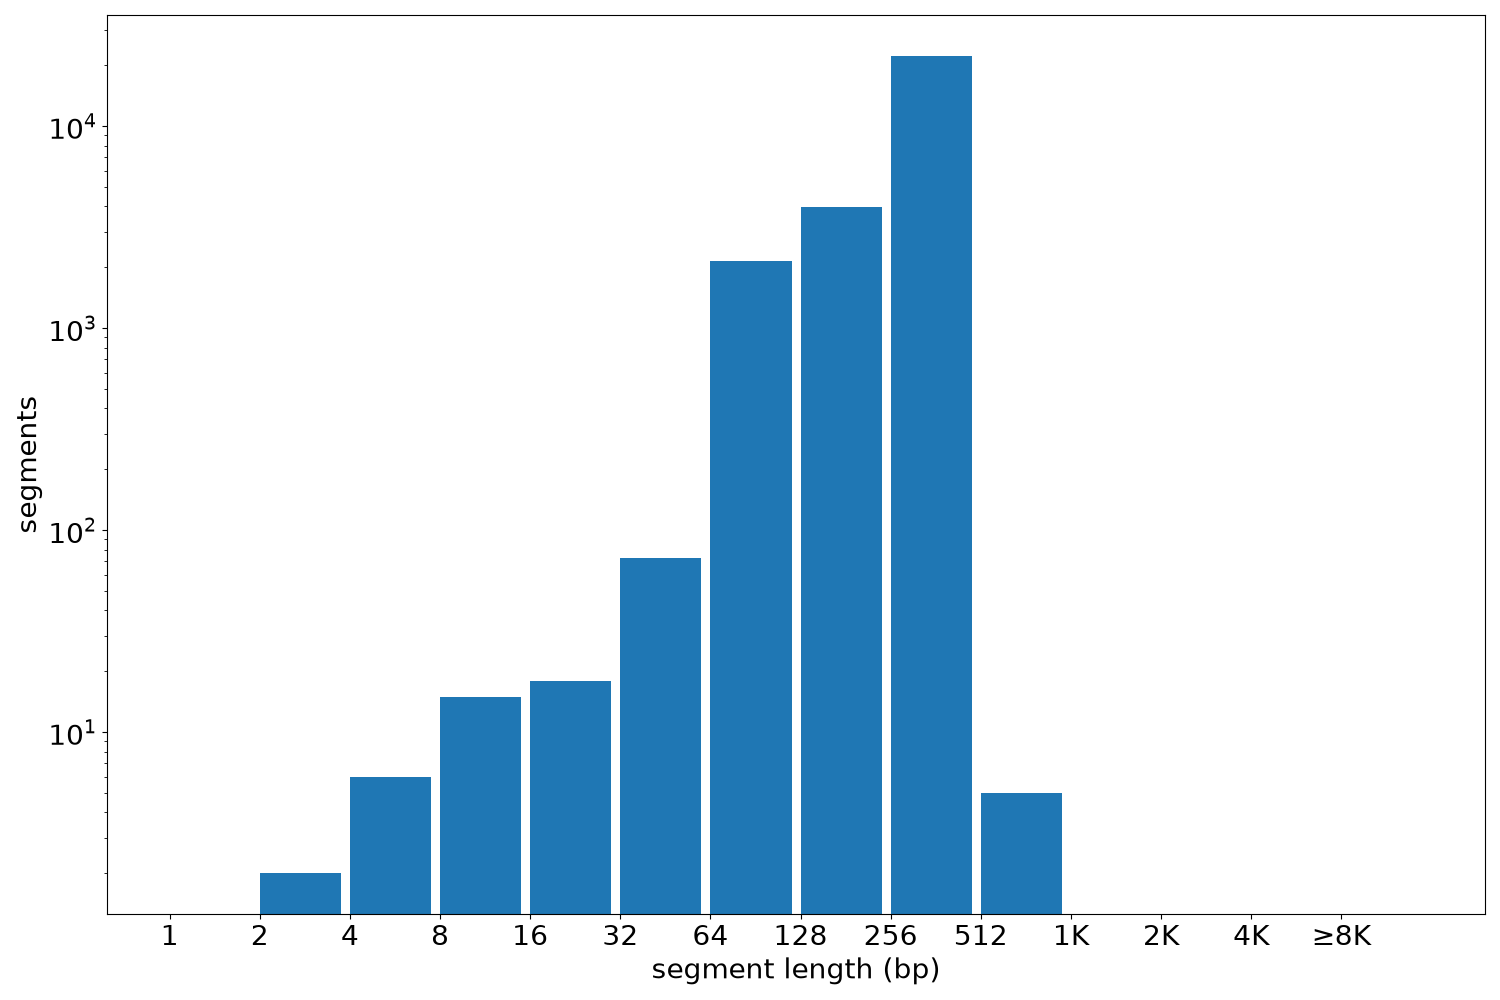
Segment lengths
| segments | min | max | mean | median | |
|---|---|---|---|---|---|
| segments | 28506 | 2 | 631 | 288.18 | 324 |
Files
| Filename | Size | md5 |
|---|---|---|
| ENCFF806TIM.bed.gz | 441.99 KB | be18a4652cf9648207ba9963b65a34c5 |
| ENCFF806TIM.tabix.bed.gz | 329.92 KB | c6adcb4a0ac94c16035c0feb476c601e |
| ENCFF806TIM.tabix.bed.gz.tbi | 157.18 KB | 13ba4fdbd5b0a0640c9b82cd80cc1c36 |
| genomic_resource.yaml | 4.42 KB | 6e50527e7fd73de7ef33e089a99d1f82 |
| statistics/ |