Resource
| Id | Histone_ChIP-seq/ENCSR849APH |
|---|---|
| Type | position_score |
| Version | 0 |
| Summary | Histone_ChIP-seq ENCSR849APH [biosample_summary="Homo sapiens PC-3" and target="H3K36me3"] |
| Description |
status: released biological_replicates: Rep 1, Rep 2 summary: output_type: pseudoreplicated peaks audit_internal_action: Released analysis {ENCAN700XNH|/analyses/ENCAN700XNH/} has in progress subobject document {1ba694f1-9c70-4b50-a66d-9df3284e76ff|/documents/1ba694f1-9c70-4b50-a66d-9df3284e76ff/} audit_internal_action: Released analysis {ENCAN700XNH|/analyses/ENCAN700XNH/} has in progress subobject quality standard {encode4-histone-chip|/quality-standards/encode4-histone-chip/} audit_warning: Processed alignments file {ENCFF427IIZ|/files/ENCFF427IIZ/} processed by ChIP-seq ENCODE4 v1.6.1 GRCh38 pipeline has 44095606 usable fragments. The minimum ENCODE standard for each replicate in a ChIP-seq experiment targeting H3K36me3-human and investigated as a broad histone mark is 20 million usable fragments. The recommended value is > 45 million, but > 35 million is acceptable. (See {ENCODE ChIP-seq data standards|/data-standards/chip-seq/}) |
| Labels |
|
Scores (1)
| ID | Type | Default annotation | Description | Histogram | Range | Summary |
|---|---|---|---|---|---|---|
| Histone_ChIP-seq_ENCSR849APH | float |
Histone_ChIP-seq_ENCSR849APH |
Histone_ChIP-seq ENCSR849APH [biosample_summary="Homo sapiens PC-3" and target="H3K36me3"]
|
 |
[1.35, 14.5] |
|
n counts base pairs; sd is the population standard deviation.
Coverage
| Chromosome | Covered positions | Covered % | Segments |
|---|---|---|---|
| all chromosomes | 77134086 | 2.40% | 100139 |
| chr1 | 9285061 | 3.73% | 11677 |
| chr2 | 6735576 | 2.78% | 9212 |
| chr3 | 5678311 | 2.86% | 7667 |
| chr4 | 2108776 | 1.11% | 2992 |
| chr5 | 3751494 | 2.07% | 4768 |
| chr6 | 2724465 | 1.60% | 3789 |
| chr7 | 3292588 | 2.07% | 4618 |
| chr8 | 4193780 | 2.89% | 4854 |
| chr9 | 1851456 | 1.34% | 2604 |
| chr10 | 3318076 | 2.48% | 4056 |
| chr11 | 4479790 | 3.32% | 5730 |
| chr12 | 4900696 | 3.68% | 6413 |
| chr13 | 1037912 | 0.91% | 1560 |
| chr14 | 3129015 | 2.92% | 4167 |
| chr15 | 2554089 | 2.50% | 3504 |
| chr16 | 1554618 | 1.72% | 2173 |
| chr17 | 3957506 | 4.75% | 5078 |
| chr18 | 1347805 | 1.68% | 1885 |
| chr19 | 4696043 | 8.01% | 5032 |
| chr20 | 2905872 | 4.51% | 3462 |
| chr21 | 1269044 | 2.72% | 1606 |
| chr22 | 832121 | 1.64% | 1182 |
| chrX | 1529992 | 0.98% | 2110 |
| 3343 contigs with no values (186304500 bp) | 0 | 0.00% | 0 |
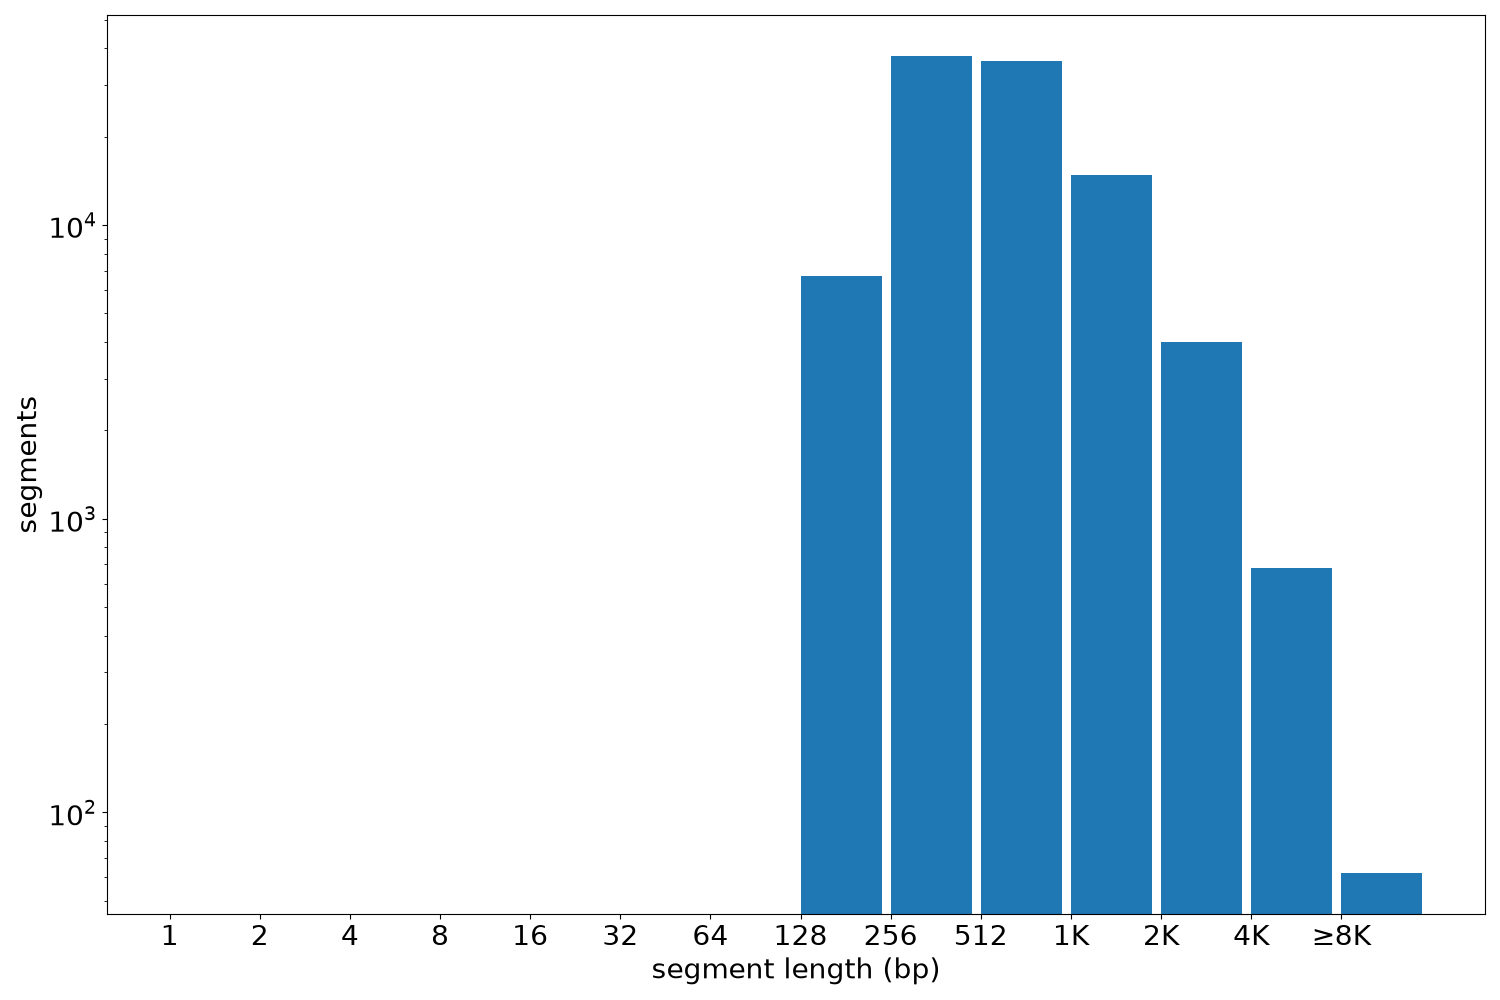
Segment lengths
| segments | min | max | mean | median | |
|---|---|---|---|---|---|
| segments | 100139 | 150 | 20879 | 770.27 | 557 |
Files
| Filename | Size | md5 |
|---|---|---|
| ENCFF390LQT.bed.gz | 2.17 MB | ddd75bc92c503f1a8b228f1e82da5282 |
| ENCFF390LQT.tabix.bed.gz | 1018.42 KB | b5fb37b25ea763569ed8435969fa8933 |
| ENCFF390LQT.tabix.bed.gz.tbi | 160.93 KB | 0ef58365c96348493b97394cd0480429 |
| genomic_resource.yaml | 2.09 KB | 360a8282d9608c8ff8f302262dfed96c |
| statistics/ |