Resource
| Id | Histone_ChIP-seq/ENCSR804SRO |
|---|---|
| Type | position_score |
| Version | 0 |
| Summary | Histone_ChIP-seq ENCSR804SRO [biosample_summary="Homo sapiens IMR-90" and target="H4K20me1"] |
| Description |
status: released biological_replicates: Rep 1, Rep 2 summary: output_type: replicated peaks audit_internal_action: Archived analysis {ENCAN162KXD|/analyses/ENCAN162KXD/} has in progress subobject quality standard {encode3-histone-chip|/quality-standards/encode3-histone-chip/} audit_not_compliant: Processed alignments file {ENCFF487XYM|/files/ENCFF487XYM/} processed by ChIP-seq ENCODE3 hg19 pipeline has 5718816 usable fragments. The minimum ENCODE standard for each replicate in a ChIP-seq experiment targeting H4K20me1-human and investigated as a broad histone mark is 20 million usable fragments. The recommended value is > 45 million, but > 35 million is acceptable. (See {ENCODE ChIP-seq data standards|/data-standards/chip-seq/}) audit_not_compliant: Processed alignments file {ENCFF991DZC|/files/ENCFF991DZC/} processed by ChIP-seq ENCODE3 hg19 pipeline has 27119067 usable fragments. The minimum ENCODE standard for each replicate in a ChIP-seq experiment targeting H4K20me1-human and investigated as a broad histone mark is 20 million usable fragments. The recommended value is > 45 million, but > 35 million is acceptable. (See {ENCODE ChIP-seq data standards|/data-standards/chip-seq/}) |
| Labels |
|
Scores (1)
| ID | Type | Default annotation | Description | Histogram | Range | Summary |
|---|---|---|---|---|---|---|
| Histone_ChIP-seq_ENCSR804SRO | float |
Histone_ChIP-seq_ENCSR804SRO |
Histone_ChIP-seq ENCSR804SRO [biosample_summary="Homo sapiens IMR-90" and target="H4K20me1"]
|
 |
[1.44, 41.7] |
|
n counts base pairs; sd is the population standard deviation.
Coverage
| Chromosome | Covered positions | Covered % | Segments |
|---|---|---|---|
| all chromosomes | 54337539 | 1.69% | 158188 |
| chr1 | 4817111 | 1.93% | 14137 |
| chr2 | 4277484 | 1.77% | 12183 |
| chr3 | 3215522 | 1.62% | 9947 |
| chr4 | 1702602 | 0.90% | 5521 |
| chr5 | 2812546 | 1.55% | 7852 |
| chr6 | 2206459 | 1.29% | 7030 |
| chr7 | 2728742 | 1.71% | 8347 |
| chr8 | 2170328 | 1.50% | 6291 |
| chr9 | 2462998 | 1.78% | 7057 |
| chr10 | 2832216 | 2.12% | 8321 |
| chr11 | 2812783 | 2.08% | 8169 |
| chr12 | 2462570 | 1.85% | 7613 |
| chr13 | 1249650 | 1.09% | 3847 |
| chr14 | 1871158 | 1.75% | 5515 |
| chr15 | 2087183 | 2.05% | 6299 |
| chr16 | 2734414 | 3.03% | 7383 |
| chr17 | 3268808 | 3.93% | 8855 |
| chr18 | 874373 | 1.09% | 2827 |
| chr19 | 2782191 | 4.75% | 6893 |
| chr20 | 1800005 | 2.79% | 4970 |
| chr21 | 706017 | 1.51% | 1918 |
| chr22 | 1740239 | 3.42% | 4839 |
| chrX | 722140 | 0.46% | 2374 |
| 3343 contigs with no values (186304500 bp) | 0 | 0.00% | 0 |
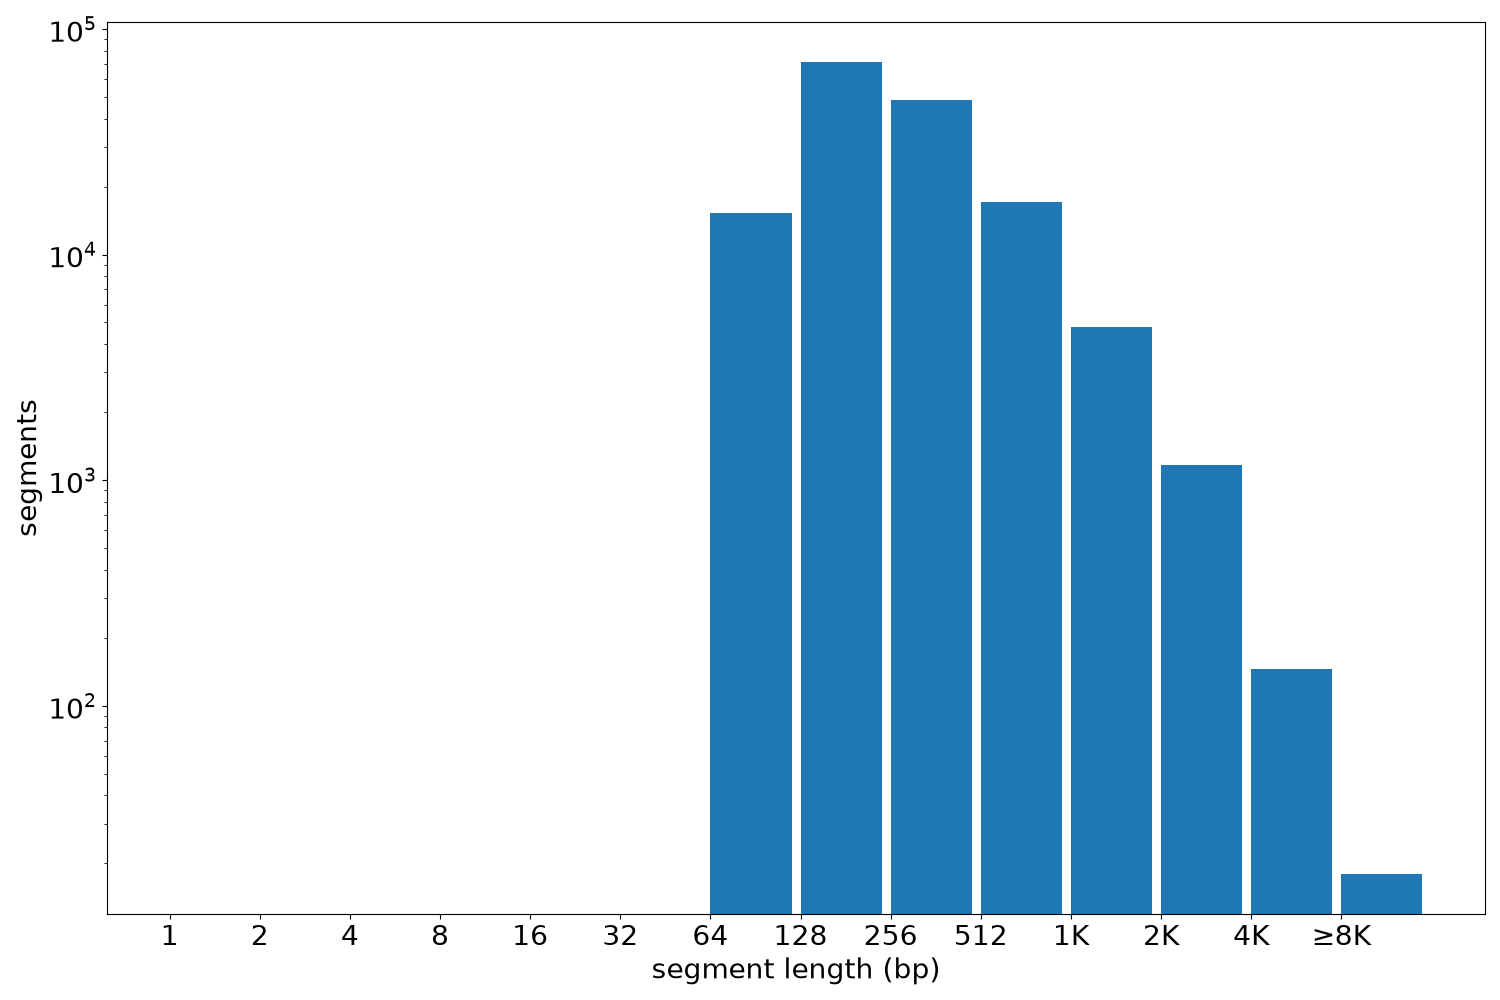
Segment lengths
| segments | min | max | mean | median | |
|---|---|---|---|---|---|
| segments | 158188 | 95 | 14604 | 343.5 | 237 |
Files
| Filename | Size | md5 |
|---|---|---|
| ENCFF602PRJ.bed.gz | 3.38 MB | d3b4fc2aaa2bc73e2c012c006c0b5cdd |
| ENCFF602PRJ.tabix.bed.gz | 1.54 MB | ef3af9d23438413468f1a780d229696b |
| ENCFF602PRJ.tabix.bed.gz.tbi | 213.32 KB | 35caa345282b8f0ab6b53f236cbe376c |
| genomic_resource.yaml | 2.37 KB | 95ad7679ed33668dc88a6cf62228e3a9 |
| statistics/ |