Resource
| Id | Histone_ChIP-seq/ENCSR440BZV |
|---|---|
| Type | position_score |
| Version | 0 |
| Summary | Histone_ChIP-seq ENCSR440BZV [biosample_summary="Homo sapiens H9" and target="H3K14ac"] |
| Description |
status: released biological_replicates: Rep 1, Rep 2 summary: output_type: pseudoreplicated peaks audit_internal_action: Released analysis {ENCAN203BWO|/analyses/ENCAN203BWO/} has in progress subobject document {99f61483-162b-465f-a36c-d9bf5e9206ad|/documents/99f61483-162b-465f-a36c-d9bf5e9206ad/} audit_internal_action: Released analysis {ENCAN203BWO|/analyses/ENCAN203BWO/} has in progress subobject quality standard {encode4-histone-chip|/quality-standards/encode4-histone-chip/} audit_not_compliant: Processed alignments file {ENCFF997SKW|/files/ENCFF997SKW/} processed by ChIP-seq ENCODE4 v1.6.1 GRCh38 pipeline has 8471634 usable fragments. The minimum ENCODE standard for each replicate in a ChIP-seq experiment targeting H3K14ac-human and investigated as a transcription factor is 10 million usable fragments. The recommended value is > 20 million, but > 10 million is acceptable. (See {ENCODE ChIP-seq data standards|/data-standards/chip-seq/} ) |
| Labels |
|
Scores (1)
| ID | Type | Default annotation | Description | Histogram | Range | Summary |
|---|---|---|---|---|---|---|
| Histone_ChIP-seq_ENCSR440BZV | float |
Histone_ChIP-seq_ENCSR440BZV |
Histone_ChIP-seq ENCSR440BZV [biosample_summary="Homo sapiens H9" and target="H3K14ac"]
|
 |
[1.76, 37.8] |
|
n counts base pairs; sd is the population standard deviation.
Coverage
| Chromosome | Covered positions | Covered % | Segments |
|---|---|---|---|
| all chromosomes | 15126966 | 0.47% | 48148 |
| chr1 | 1529263 | 0.61% | 4793 |
| chr2 | 1093467 | 0.45% | 3564 |
| chr3 | 847575 | 0.43% | 2683 |
| chr4 | 567656 | 0.30% | 1785 |
| chr5 | 767739 | 0.42% | 2405 |
| chr6 | 829045 | 0.49% | 2536 |
| chr7 | 749990 | 0.47% | 2427 |
| chr8 | 598176 | 0.41% | 1972 |
| chr9 | 623130 | 0.45% | 2053 |
| chr10 | 727260 | 0.54% | 2379 |
| chr11 | 829052 | 0.61% | 2646 |
| chr12 | 740144 | 0.56% | 2224 |
| chr13 | 319216 | 0.28% | 1066 |
| chr14 | 537077 | 0.50% | 1699 |
| chr15 | 509171 | 0.50% | 1617 |
| chr16 | 595477 | 0.66% | 1947 |
| chr17 | 793345 | 0.95% | 2480 |
| chr18 | 303653 | 0.38% | 1032 |
| chr19 | 780003 | 1.33% | 2320 |
| chr20 | 465099 | 0.72% | 1568 |
| chr21 | 168770 | 0.36% | 566 |
| chr22 | 420208 | 0.83% | 1346 |
| chrX | 332450 | 0.21% | 1040 |
| 3343 contigs with no values (186304500 bp) | 0 | 0.00% | 0 |
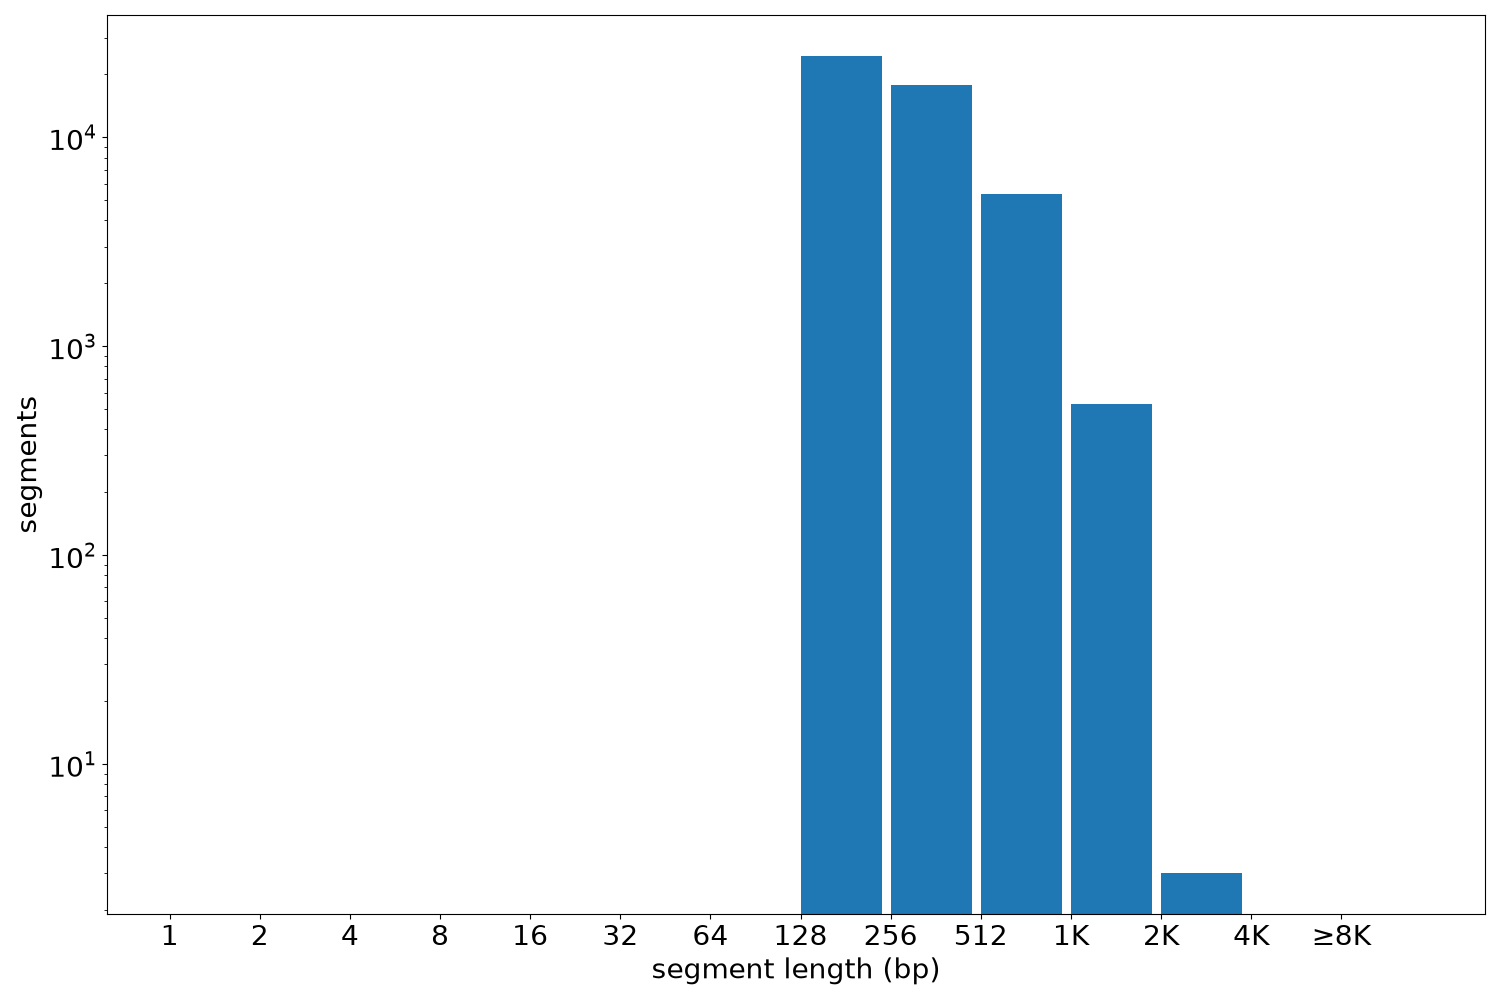
Segment lengths
| segments | min | max | mean | median | |
|---|---|---|---|---|---|
| segments | 48148 | 135 | 3257 | 314.18 | 252 |
Files
| Filename | Size | md5 |
|---|---|---|
| ENCFF244ENN.bed.gz | 1.04 MB | c9ce45c955136ad949ffb27d3030ba54 |
| ENCFF244ENN.tabix.bed.gz | 497.65 KB | 1951fdb3b72f2b2ca3c0242f10c9c799 |
| ENCFF244ENN.tabix.bed.gz.tbi | 239.44 KB | 8238620ff65e877dea6dd7ebb7140f80 |
| genomic_resource.yaml | 2.09 KB | ec8aca8e4bff867d08f6f4f55a938df1 |
| statistics/ |