Resource
| Id | Histone_ChIP-seq/ENCSR374RZR |
|---|---|
| Type | position_score |
| Version | 0 |
| Summary | Histone_ChIP-seq ENCSR374RZR [biosample_summary="Homo sapiens MCF-7" and target="H3K9me2"] |
| Description |
status: released biological_replicates: Rep 1, Rep 2 summary: output_type: pseudoreplicated peaks audit_internal_action: Released analysis {ENCAN579WOJ|/analyses/ENCAN579WOJ/} has in progress subobject quality standard {encode4-histone-chip|/quality-standards/encode4-histone-chip/} audit_internal_action: Released analysis {ENCAN579WOJ|/analyses/ENCAN579WOJ/} has in progress subobject document {c8f1146d-d68a-4506-822a-ede4f0d34e2a|/documents/c8f1146d-d68a-4506-822a-ede4f0d34e2a/} audit_not_compliant: Processed alignments file {ENCFF418SFP|/files/ENCFF418SFP/} processed by ChIP-seq ENCODE4 v1.6.1 GRCh38 pipeline has 15152718 usable fragments. The minimum ENCODE standard for each replicate in a ChIP-seq experiment targeting H3K9me2-human and investigated as a broad histone mark is 20 million usable fragments. The recommended value is > 45 million, but > 35 million is acceptable. (See {ENCODE ChIP-seq data standards|/data-standards/chip-seq/}) audit_not_compliant: Processed alignments file {ENCFF249TCH|/files/ENCFF249TCH/} processed by ChIP-seq ENCODE4 v1.6.1 GRCh38 pipeline has 21241620 usable fragments. The minimum ENCODE standard for each replicate in a ChIP-seq experiment targeting H3K9me2-human and investigated as a broad histone mark is 20 million usable fragments. The recommended value is > 45 million, but > 35 million is acceptable. (See {ENCODE ChIP-seq data standards|/data-standards/chip-seq/}) |
| Labels |
|
Scores (1)
| ID | Type | Default annotation | Description | Histogram | Range | Summary |
|---|---|---|---|---|---|---|
| Histone_ChIP-seq_ENCSR374RZR | float |
Histone_ChIP-seq_ENCSR374RZR |
Histone_ChIP-seq ENCSR374RZR [biosample_summary="Homo sapiens MCF-7" and target="H3K9me2"]
|
 |
[1.41, 5] |
|
n counts base pairs; sd is the population standard deviation.
Coverage
| Chromosome | Covered positions | Covered % | Segments |
|---|---|---|---|
| all chromosomes | 393726 | 0.01% | 887 |
| chr1 | 24200 | 0.01% | 48 |
| chr2 | 20430 | 0.01% | 53 |
| chr3 | 55731 | 0.03% | 135 |
| chr4 | 4163 | <0.01% | 11 |
| chr5 | 25930 | 0.01% | 74 |
| chr6 | 12013 | 0.01% | 32 |
| chr7 | 20781 | 0.01% | 53 |
| chr8 | 30937 | 0.02% | 81 |
| chr9 | 10351 | 0.01% | 26 |
| chr10 | 6364 | <0.01% | 17 |
| chr11 | 2479 | <0.01% | 7 |
| chr12 | 14744 | 0.01% | 40 |
| chr13 | 5862 | 0.01% | 12 |
| chr14 | 16388 | 0.02% | 44 |
| chr15 | 9309 | 0.01% | 23 |
| chr16 | 4917 | 0.01% | 14 |
| chr17 | 48299 | 0.06% | 82 |
| chr18 | 414 | <0.01% | 1 |
| chr19 | 1002 | <0.01% | 3 |
| chr20 | 75339 | 0.12% | 121 |
| chr21 | 2314 | <0.01% | 6 |
| chrX | 1759 | <0.01% | 4 |
| 3344 contigs with no values (237122968 bp) | 0 | 0.00% | 0 |
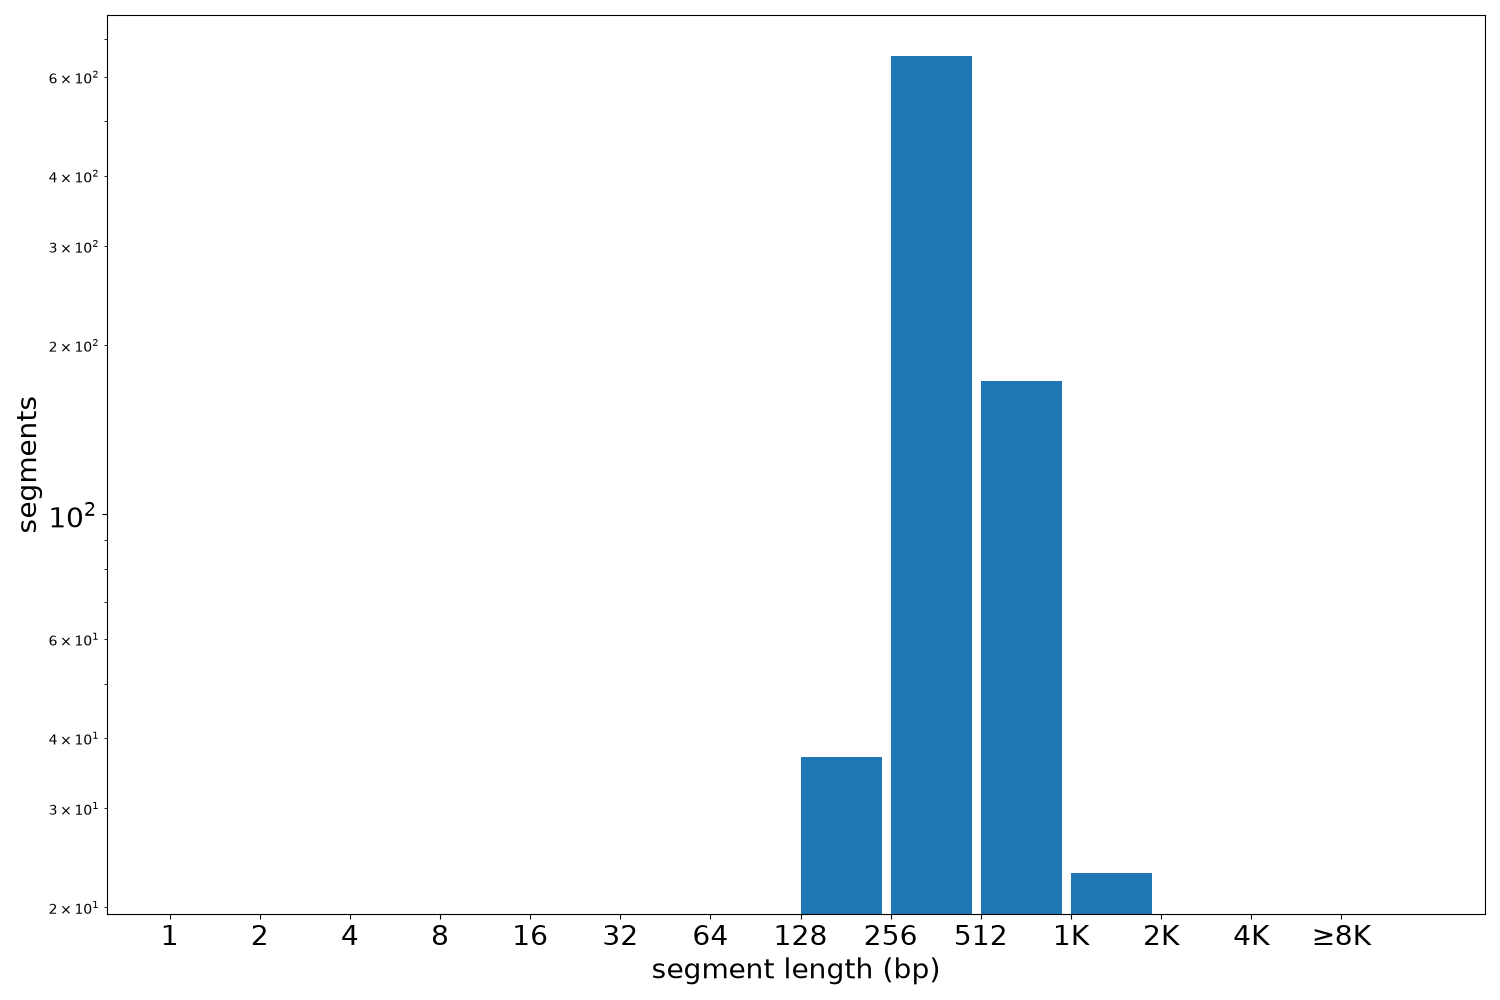
Segment lengths
| segments | min | max | mean | median | |
|---|---|---|---|---|---|
| segments | 887 | 208 | 1753 | 443.89 | 386 |
Files
| Filename | Size | md5 |
|---|---|---|
| ENCFF538BHD.bed.gz | 21.56 KB | d338de459a8be8a24dabface9ec8efc3 |
| ENCFF538BHD.tabix.bed.gz | 9.95 KB | e660c6d69e08ce87e389a0d8dd45b458 |
| ENCFF538BHD.tabix.bed.gz.tbi | 12.28 KB | 559e4b087eae5d01e2b471dd01579197 |
| genomic_resource.yaml | 2.61 KB | eb53518588c08d58632fdf0d0a64316b |
| statistics/ |