Resource
| Id | Histone_ChIP-seq/ENCSR065HOR |
|---|---|
| Type | position_score |
| Version | 0 |
| Summary | Histone_ChIP-seq ENCSR065HOR [biosample_summary="Homo sapiens mesenchymal stem cell originated from H1" and target="H3K4me1"] |
| Description |
status: released biological_replicates: Rep 1, Rep 2 summary: male embryo output_type: pseudoreplicated peaks audit_internal_action: Released analysis {ENCAN986XFK|/analyses/ENCAN986XFK/} has in progress subobject document {1d55ad46-9066-403c-a725-6aa4dafaa833|/documents/1d55ad46-9066-403c-a725-6aa4dafaa833/} audit_internal_action: Released analysis {ENCAN986XFK|/analyses/ENCAN986XFK/} has in progress subobject quality standard {encode4-histone-chip|/quality-standards/encode4-histone-chip/} audit_not_compliant: Processed alignments file {ENCFF362KVF|/files/ENCFF362KVF/} processed by ChIP-seq ENCODE4 v1.6.1 GRCh38 pipeline has 7991893 usable fragments. The minimum ENCODE standard for each replicate in a ChIP-seq experiment targeting H3K4me1-human and investigated as a broad histone mark is 20 million usable fragments. The recommended value is > 45 million, but > 35 million is acceptable. (See {ENCODE ChIP-seq data standards|/data-standards/chip-seq/}) audit_warning: Processed alignments file {ENCFF250JXU|/files/ENCFF250JXU/} processed by ChIP-seq ENCODE4 v1.6.1 GRCh38 pipeline has 39382995 usable fragments. The minimum ENCODE standard for each replicate in a ChIP-seq experiment targeting H3K4me1-human and investigated as a broad histone mark is 20 million usable fragments. The recommended value is > 45 million, but > 35 million is acceptable. (See {ENCODE ChIP-seq data standards|/data-standards/chip-seq/}) |
| Labels |
|
Scores (1)
| ID | Type | Default annotation | Description | Histogram | Range | Summary |
|---|---|---|---|---|---|---|
| Histone_ChIP-seq_ENCSR065HOR | float |
Histone_ChIP-seq_ENCSR065HOR |
Histone_ChIP-seq ENCSR065HOR [biosample_summary="Homo sapiens mesenchymal stem cell originated from H1" and target="H3K4me1"]
|
 |
[1.66, 26.5] |
|
n counts base pairs; sd is the population standard deviation.
Coverage
| Chromosome | Covered positions | Covered % | Segments |
|---|---|---|---|
| all chromosomes | 74777825 | 2.32% | 214734 |
| chr1 | 7177044 | 2.88% | 20190 |
| chr2 | 5718964 | 2.36% | 17393 |
| chr3 | 3974343 | 2.00% | 12674 |
| chr4 | 2466062 | 1.30% | 8174 |
| chr5 | 3299882 | 1.82% | 10353 |
| chr6 | 3357747 | 1.97% | 11127 |
| chr7 | 3559917 | 2.23% | 10712 |
| chr8 | 3049673 | 2.10% | 9584 |
| chr9 | 3791902 | 2.74% | 10286 |
| chr10 | 3811802 | 2.85% | 11226 |
| chr11 | 4293747 | 3.18% | 11319 |
| chr12 | 3153759 | 2.37% | 9394 |
| chr13 | 1587045 | 1.39% | 5344 |
| chr14 | 2364420 | 2.21% | 6671 |
| chr15 | 2568792 | 2.52% | 7482 |
| chr16 | 3502897 | 3.88% | 8823 |
| chr17 | 4911182 | 5.90% | 11941 |
| chr18 | 1421602 | 1.77% | 4725 |
| chr19 | 3813783 | 6.51% | 8715 |
| chr20 | 2477532 | 3.84% | 6698 |
| chr21 | 1001799 | 2.14% | 2774 |
| chr22 | 2530463 | 4.98% | 5927 |
| chrX | 924690 | 0.59% | 3125 |
| chrY | 18778 | 0.03% | 77 |
| 3342 contigs with no values (129077085 bp) | 0 | 0.00% | 0 |
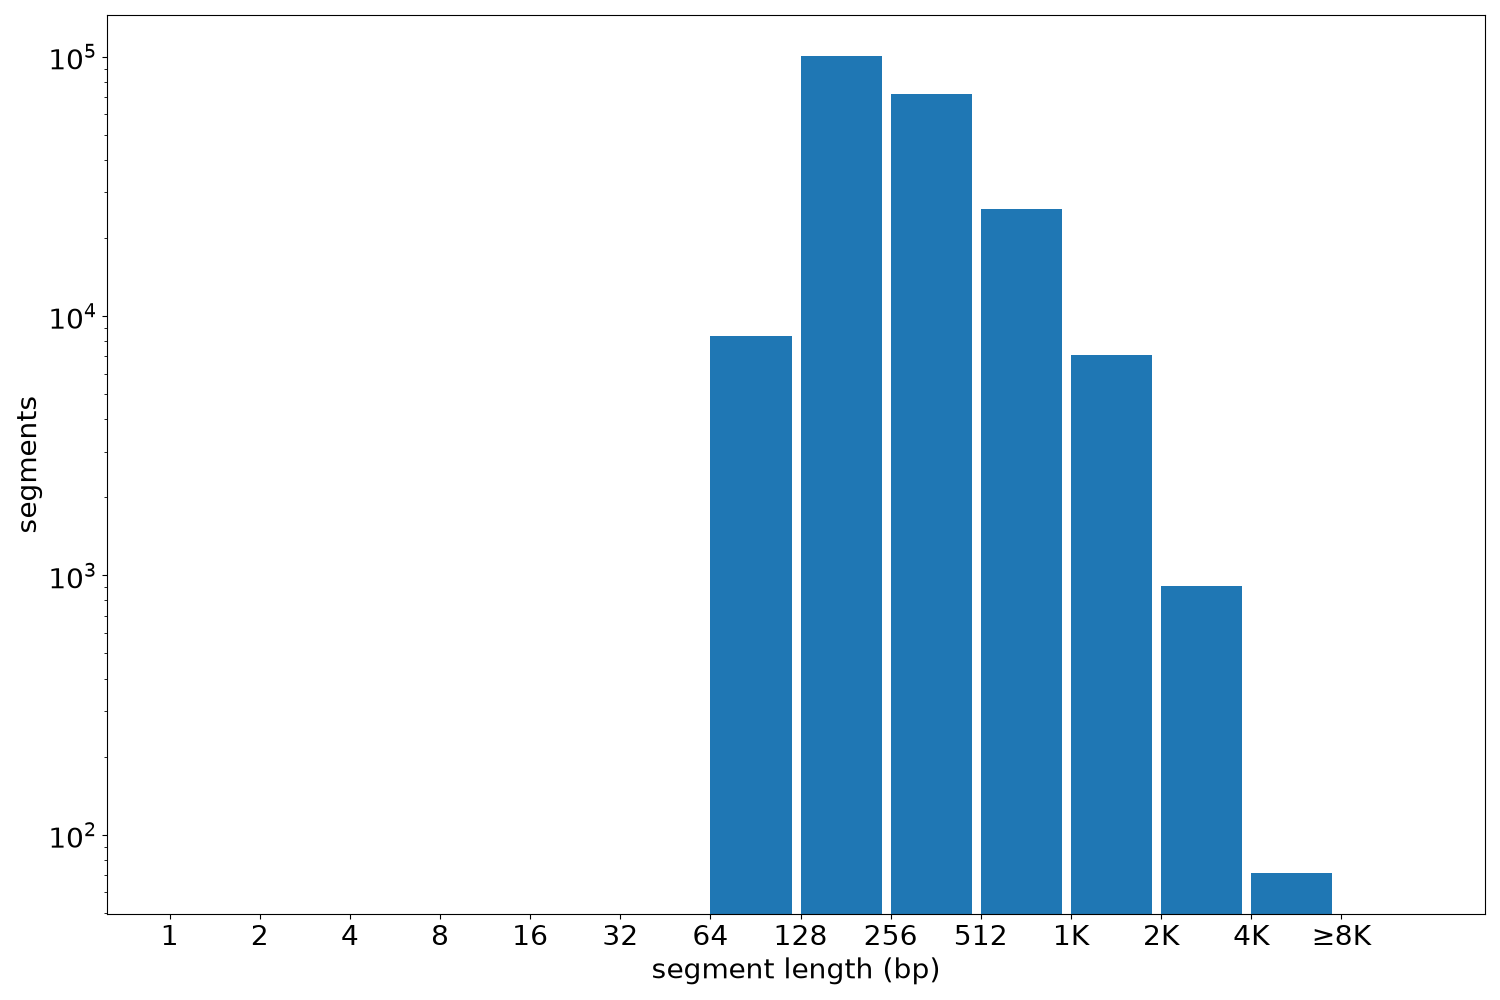
Segment lengths
| segments | min | max | mean | median | |
|---|---|---|---|---|---|
| segments | 214734 | 113 | 7789 | 348.23 | 252 |
Files
| Filename | Size | md5 |
|---|---|---|
| ENCFF905PYL.bed.gz | 4.63 MB | d4a6bd6f3c120385494105a8ccac28c8 |
| ENCFF905PYL.tabix.bed.gz | 2.1 MB | 3938368e53f356f7f0cfc8b0f413ebbd |
| ENCFF905PYL.tabix.bed.gz.tbi | 441.64 KB | 339e5119168823d0d916ae6960a379a8 |
| genomic_resource.yaml | 2.69 KB | 424adb3ec9306bfb3c7f0349e7817109 |
| statistics/ |