Resource
| Id | Histone_ChIP-seq/ENCSR047TJL |
|---|---|
| Type | position_score |
| Version | 0 |
| Summary | Histone_ChIP-seq ENCSR047TJL [biosample_summary="Homo sapiens H9" and target="H3K56ac"] |
| Description |
status: released biological_replicates: Rep 1, Rep 2 summary: output_type: pseudoreplicated peaks audit_internal_action: Released analysis {ENCAN145RCZ|/analyses/ENCAN145RCZ/} has in progress subobject quality standard {encode4-histone-chip|/quality-standards/encode4-histone-chip/} audit_internal_action: Released analysis {ENCAN145RCZ|/analyses/ENCAN145RCZ/} has in progress subobject document {7af2359c-28ac-485c-b998-02cb70761546|/documents/7af2359c-28ac-485c-b998-02cb70761546/} audit_warning: Processed alignments file {ENCFF685QVN|/files/ENCFF685QVN/} processed by ChIP-seq ENCODE4 v1.6.1 GRCh38 pipeline has 15161003 usable fragments. The minimum ENCODE standard for each replicate in a ChIP-seq experiment targeting H3K56ac-human and investigated as a transcription factor is 10 million usable fragments. The recommended value is > 20 million, but > 10 million is acceptable. (See {ENCODE ChIP-seq data standards|/data-standards/chip-seq/} ) audit_warning: Processed alignments file {ENCFF345SVV|/files/ENCFF345SVV/} processed by ChIP-seq ENCODE4 v1.6.1 GRCh38 pipeline has 14957913 usable fragments. The minimum ENCODE standard for each replicate in a ChIP-seq experiment targeting H3K56ac-human and investigated as a transcription factor is 10 million usable fragments. The recommended value is > 20 million, but > 10 million is acceptable. (See {ENCODE ChIP-seq data standards|/data-standards/chip-seq/} ) audit_warning: PBC1 (PCR Bottlenecking Coefficient 1, M1/M_distinct) is the ratio of the number of genomic locations where exactly one read maps uniquely (M1) to the number of genomic locations where some reads map (M_distinct). A PBC1 value in the range 0 - 0.5 is severe bottlenecking, 0.5 - 0.8 is moderate bottlenecking, 0.8 - 0.9 is mild bottlenecking, and > 0.9 is no bottlenecking. PBC1 value > 0.9 is recommended, but > 0.8 is acceptable. ENCODE processed alignments file {ENCFF685QVN|/files/ENCFF685QVN/} processed by ChIP-seq ENCODE4 v1.6.1 GRCh38 pipeline was generated from a library with PBC1 value of 0.85. audit_warning: PBC2 (PCR Bottlenecking Coefficient 2, M1/M2) is the ratio of the number of genomic locations where exactly one read maps uniquely (M1) to the number of genomic locations where two reads map uniquely (M2). A PBC2 value in the range 0 - 1 is severe bottlenecking, 1 - 3 is moderate bottlenecking, 3 - 10 is mild bottlenecking, > 10 is no bottlenecking. PBC2 value > 10 is recommended, but > 3 is acceptable. ENCODE processed alignments file {ENCFF685QVN|/files/ENCFF685QVN/} processed by ChIP-seq ENCODE4 v1.6.1 GRCh38 pipeline was generated from a library with PBC2 value of 6.76. audit_warning: PBC1 (PCR Bottlenecking Coefficient 1, M1/M_distinct) is the ratio of the number of genomic locations where exactly one read maps uniquely (M1) to the number of genomic locations where some reads map (M_distinct). A PBC1 value in the range 0 - 0.5 is severe bottlenecking, 0.5 - 0.8 is moderate bottlenecking, 0.8 - 0.9 is mild bottlenecking, and > 0.9 is no bottlenecking. PBC1 value > 0.9 is recommended, but > 0.8 is acceptable. ENCODE processed alignments file {ENCFF345SVV|/files/ENCFF345SVV/} processed by ChIP-seq ENCODE4 v1.6.1 GRCh38 pipeline was generated from a library with PBC1 value of 0.88. audit_warning: PBC2 (PCR Bottlenecking Coefficient 2, M1/M2) is the ratio of the number of genomic locations where exactly one read maps uniquely (M1) to the number of genomic locations where two reads map uniquely (M2). A PBC2 value in the range 0 - 1 is severe bottlenecking, 1 - 3 is moderate bottlenecking, 3 - 10 is mild bottlenecking, > 10 is no bottlenecking. PBC2 value > 10 is recommended, but > 3 is acceptable. ENCODE processed alignments file {ENCFF345SVV|/files/ENCFF345SVV/} processed by ChIP-seq ENCODE4 v1.6.1 GRCh38 pipeline was generated from a library with PBC2 value of 8.31. |
| Labels |
|
Scores (1)
| ID | Type | Default annotation | Description | Histogram | Range | Summary |
|---|---|---|---|---|---|---|
| Histone_ChIP-seq_ENCSR047TJL | float |
Histone_ChIP-seq_ENCSR047TJL |
Histone_ChIP-seq ENCSR047TJL [biosample_summary="Homo sapiens H9" and target="H3K56ac"]
|
 |
[1.72, 13.5] |
|
n counts base pairs; sd is the population standard deviation.
Coverage
| Chromosome | Covered positions | Covered % | Segments |
|---|---|---|---|
| all chromosomes | 1658465 | 0.05% | 3195 |
| chr1 | 176106 | 0.07% | 334 |
| chr2 | 128066 | 0.05% | 240 |
| chr3 | 96031 | 0.05% | 188 |
| chr4 | 77661 | 0.04% | 153 |
| chr5 | 87247 | 0.05% | 168 |
| chr6 | 103588 | 0.06% | 192 |
| chr7 | 78840 | 0.05% | 155 |
| chr8 | 64622 | 0.04% | 139 |
| chr9 | 54878 | 0.04% | 116 |
| chr10 | 72804 | 0.05% | 144 |
| chr11 | 81114 | 0.06% | 152 |
| chr12 | 90075 | 0.07% | 158 |
| chr13 | 33565 | 0.03% | 65 |
| chr14 | 50156 | 0.05% | 100 |
| chr15 | 43821 | 0.04% | 89 |
| chr16 | 50695 | 0.06% | 104 |
| chr17 | 71557 | 0.09% | 136 |
| chr18 | 31311 | 0.04% | 66 |
| chr19 | 73748 | 0.13% | 138 |
| chr20 | 49087 | 0.08% | 90 |
| chr21 | 16092 | 0.03% | 32 |
| chr22 | 36852 | 0.07% | 71 |
| chrX | 90218 | 0.06% | 164 |
| chrY | 331 | <0.01% | 1 |
| 3342 contigs with no values (129077085 bp) | 0 | 0.00% | 0 |
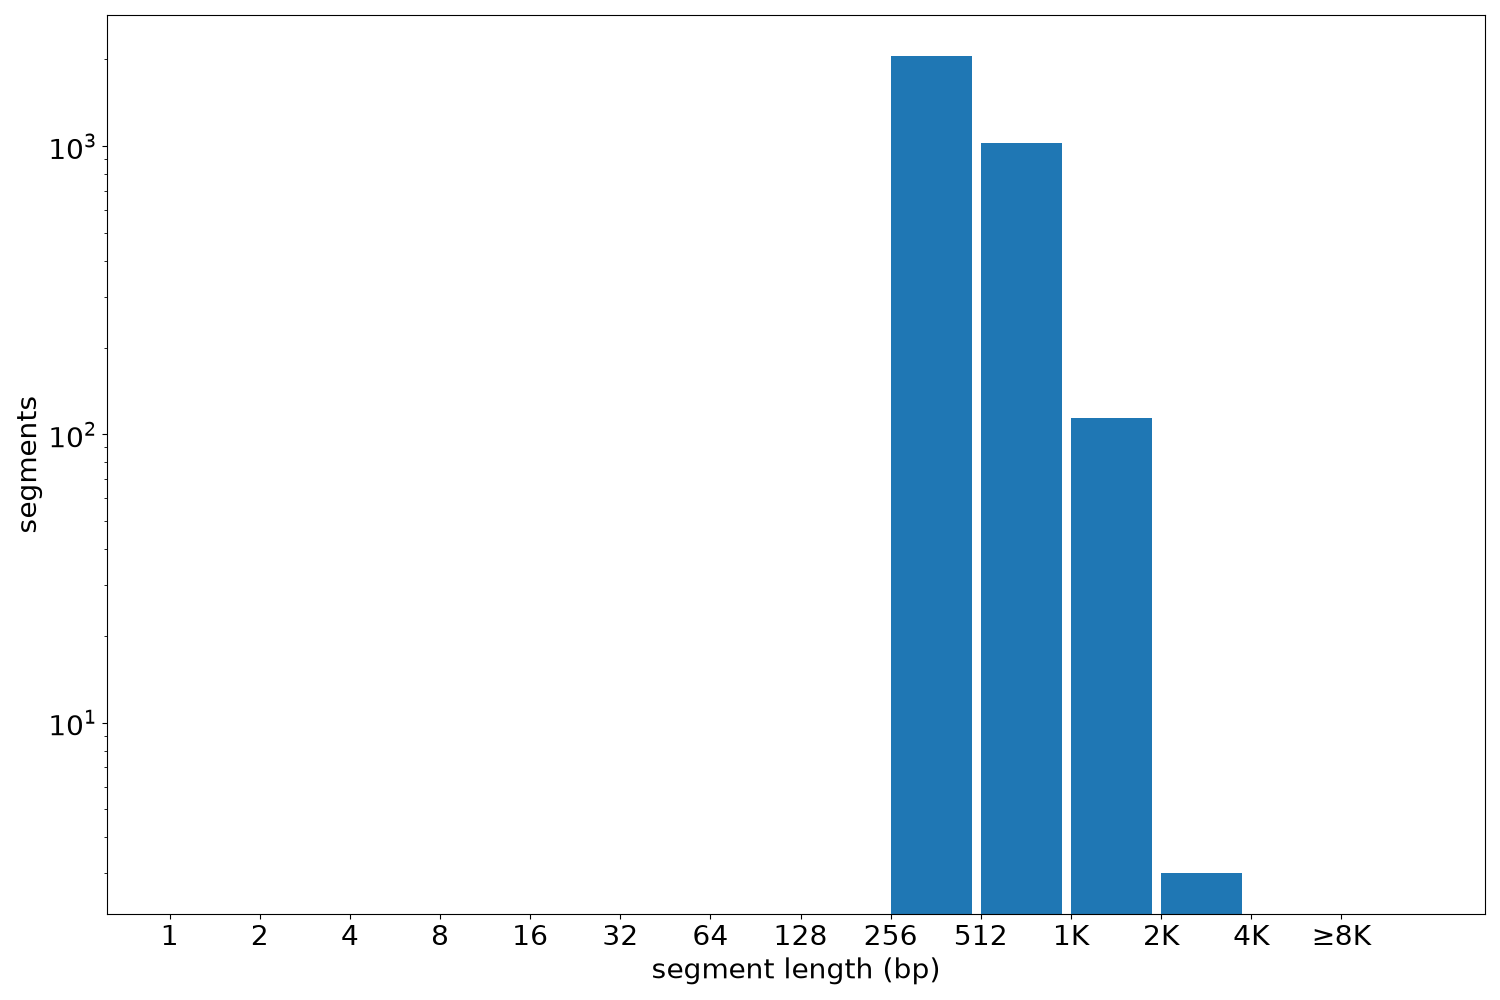
Segment lengths
| segments | min | max | mean | median | |
|---|---|---|---|---|---|
| segments | 3195 | 283 | 2562 | 519.08 | 454 |
Files
| Filename | Size | md5 |
|---|---|---|
| ENCFF459XPD.bed.gz | 72.64 KB | 20a33daf8405ee14d59307c26485dc69 |
| ENCFF459XPD.tabix.bed.gz | 35.62 KB | 3e3276f61b1670bece2422d9b36748b1 |
| ENCFF459XPD.tabix.bed.gz.tbi | 35.42 KB | d965988f9cec021cfe0a234746615e74 |
| genomic_resource.yaml | 5.22 KB | 79bc516396a0f604df01905b582e78ae |
| statistics/ |