Resource
| Id | Histone_ChIP-seq/ENCSR000FCU |
|---|---|
| Type | position_score |
| Version | 0 |
| Summary | Histone_ChIP-seq ENCSR000FCU [biosample_summary="Homo sapiens SK-N-SH" and target="H3K27ac"] |
| Description |
status: released biological_replicates: Rep 1, Rep 2 summary: output_type: pseudoreplicated peaks audit_internal_action: Released analysis {ENCAN615AXV|/analyses/ENCAN615AXV/} has in progress subobject quality standard {encode4-histone-chip|/quality-standards/encode4-histone-chip/} audit_internal_action: Released analysis {ENCAN615AXV|/analyses/ENCAN615AXV/} has in progress subobject document {27b5f19c-66cd-4370-9afa-1bf425e8de29|/documents/27b5f19c-66cd-4370-9afa-1bf425e8de29/} audit_warning: Processed alignments file {ENCFF329HOS|/files/ENCFF329HOS/} processed by ChIP-seq ENCODE4 v1.5.1 GRCh38 pipeline has 16983287 usable fragments. The minimum ENCODE standard for each replicate in a ChIP-seq experiment targeting H3K27ac-human and investigated as a narrow histone mark is 10 million usable fragments. The recommended value is > 20 million, but > 10 million is acceptable. (See {ENCODE ChIP-seq data standards|/data-standards/chip-seq/}) |
| Labels |
|
Scores (1)
| ID | Type | Default annotation | Description | Histogram | Range | Summary |
|---|---|---|---|---|---|---|
| Histone_ChIP-seq_ENCSR000FCU | float |
Histone_ChIP-seq_ENCSR000FCU |
Histone_ChIP-seq ENCSR000FCU [biosample_summary="Homo sapiens SK-N-SH" and target="H3K27ac"]
|
 |
[1.58, 79.8] |
|
n counts base pairs; sd is the population standard deviation.
Coverage
| Chromosome | Covered positions | Covered % | Segments |
|---|---|---|---|
| all chromosomes | 98327474 | 3.06% | 109149 |
| chr1 | 10439462 | 4.19% | 11205 |
| chr2 | 8429576 | 3.48% | 9415 |
| chr3 | 6668143 | 3.36% | 7519 |
| chr4 | 4941370 | 2.60% | 5676 |
| chr5 | 6205412 | 3.42% | 6654 |
| chr6 | 5617348 | 3.29% | 6196 |
| chr7 | 6068488 | 3.81% | 6455 |
| chr8 | 3933984 | 2.71% | 4469 |
| chr9 | 4109035 | 2.97% | 4598 |
| chr10 | 4944448 | 3.70% | 5399 |
| chr11 | 5390681 | 3.99% | 5662 |
| chr12 | 4807166 | 3.61% | 5384 |
| chr13 | 2639293 | 2.31% | 3188 |
| chr14 | 3084095 | 2.88% | 3225 |
| chr15 | 3069275 | 3.01% | 3512 |
| chr16 | 2736952 | 3.03% | 3193 |
| chr17 | 4413853 | 5.30% | 4462 |
| chr18 | 1956525 | 2.43% | 2227 |
| chr19 | 2327367 | 3.97% | 2930 |
| chr20 | 2215778 | 3.44% | 2539 |
| chr21 | 886197 | 1.90% | 1075 |
| chr22 | 1693081 | 3.33% | 1863 |
| chrX | 1749945 | 1.12% | 2303 |
| 3343 contigs with no values (186304500 bp) | 0 | 0.00% | 0 |
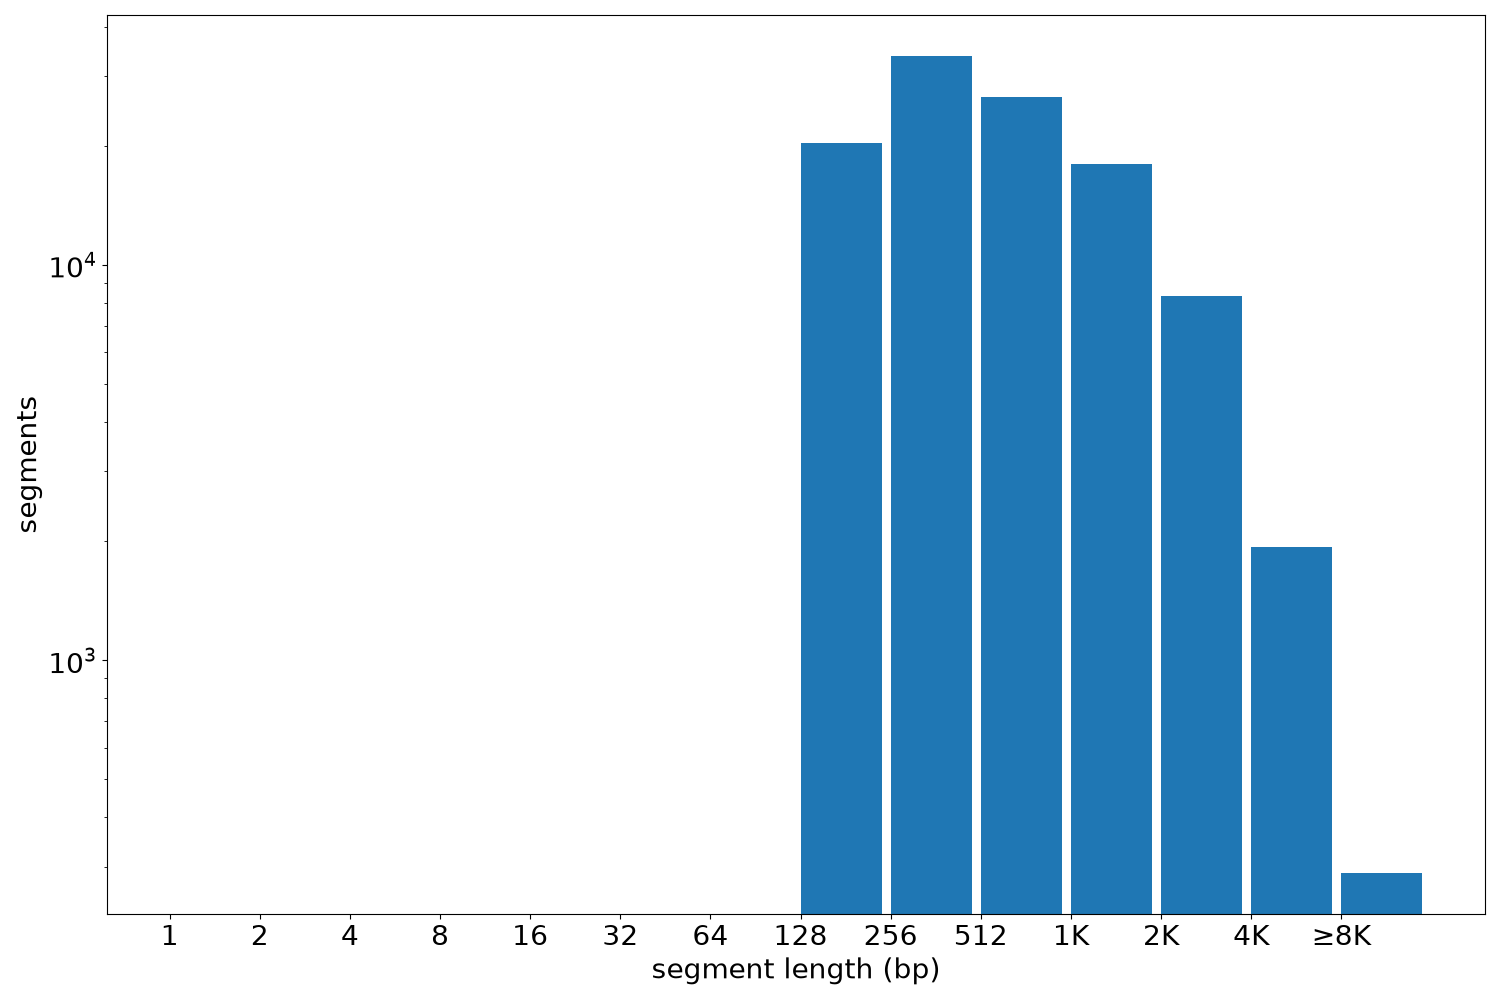
Segment lengths
| segments | min | max | mean | median | |
|---|---|---|---|---|---|
| segments | 109149 | 153 | 43125 | 900.86 | 518 |
Files
| Filename | Size | md5 |
|---|---|---|
| ENCFF188BQP.bed.gz | 2.4 MB | 4c953c6729a7a3066f09e6b881691bec |
| ENCFF188BQP.tabix.bed.gz | 1.1 MB | 3ff0191a41db2887ca4e2027feefbc0c |
| ENCFF188BQP.tabix.bed.gz.tbi | 307.31 KB | 8f7db4cde0dc01451179cac94dd4f44b |
| genomic_resource.yaml | 2.1 KB | dde2820d7c7ece082b817e01f19c0180 |
| statistics/ |