Resource
| Id | Histone_ChIP-seq/ENCSR000AKM |
|---|---|
| Type | position_score |
| Version | 0 |
| Summary | Histone_ChIP-seq ENCSR000AKM [biosample_summary="Homo sapiens endothelial cell of umbilical vein newborn" and target="H3K4me2"] |
| Description |
status: released biological_replicates: Rep 1, Rep 2 summary: newborn output_type: pseudoreplicated peaks audit_internal_action: Released analysis {ENCAN253XYY|/analyses/ENCAN253XYY/} has in progress subobject quality standard {encode4-histone-chip|/quality-standards/encode4-histone-chip/} audit_internal_action: Released analysis {ENCAN253XYY|/analyses/ENCAN253XYY/} has in progress subobject document {f5c8744e-c2ad-4fb2-ba0e-3af71bbc88f8|/documents/f5c8744e-c2ad-4fb2-ba0e-3af71bbc88f8/} audit_not_compliant: Processed alignments file {ENCFF124JVO|/files/ENCFF124JVO/} processed by ChIP-seq ENCODE4 v1.6.1 GRCh38 pipeline has 8344541 usable fragments. The minimum ENCODE standard for each replicate in a ChIP-seq experiment targeting H3K4me2-human and investigated as a narrow histone mark is 10 million usable fragments. The recommended value is > 20 million, but > 10 million is acceptable. (See {ENCODE ChIP-seq data standards|/data-standards/chip-seq/}) audit_not_compliant: Processed alignments file {ENCFF952NEV|/files/ENCFF952NEV/} processed by ChIP-seq ENCODE4 v1.6.1 GRCh38 pipeline has 9463780 usable fragments. The minimum ENCODE standard for each replicate in a ChIP-seq experiment targeting H3K4me2-human and investigated as a narrow histone mark is 10 million usable fragments. The recommended value is > 20 million, but > 10 million is acceptable. (See {ENCODE ChIP-seq data standards|/data-standards/chip-seq/}) |
| Labels |
|
Scores (1)
| ID | Type | Default annotation | Description | Histogram | Range | Summary |
|---|---|---|---|---|---|---|
| Histone_ChIP-seq_ENCSR000AKM | float |
Histone_ChIP-seq_ENCSR000AKM |
Histone_ChIP-seq ENCSR000AKM [biosample_summary="Homo sapiens endothelial cell of umbilical vein newborn" and target="H3K4me2"]
|
 |
[1.65, 42.9] |
|
n counts base pairs; sd is the population standard deviation.
Coverage
| Chromosome | Covered positions | Covered % | Segments |
|---|---|---|---|
| all chromosomes | 67306575 | 2.09% | 73264 |
| chr1 | 6337180 | 2.55% | 6757 |
| chr2 | 5206276 | 2.15% | 5607 |
| chr3 | 4567100 | 2.30% | 4874 |
| chr4 | 3522503 | 1.85% | 3704 |
| chr5 | 3737013 | 2.06% | 4002 |
| chr6 | 4391146 | 2.57% | 4591 |
| chr7 | 3420220 | 2.15% | 3717 |
| chr8 | 2954280 | 2.04% | 3232 |
| chr9 | 2791687 | 2.02% | 3035 |
| chr10 | 3134526 | 2.34% | 3383 |
| chr11 | 3282412 | 2.43% | 3586 |
| chr12 | 3752539 | 2.82% | 4019 |
| chr13 | 1863097 | 1.63% | 2055 |
| chr14 | 2178705 | 2.04% | 2376 |
| chr15 | 2277675 | 2.23% | 2485 |
| chr16 | 1967624 | 2.18% | 2229 |
| chr17 | 2892599 | 3.47% | 3268 |
| chr18 | 1457592 | 1.81% | 1564 |
| chr19 | 2281956 | 3.89% | 2620 |
| chr20 | 1591713 | 2.47% | 1816 |
| chr21 | 752426 | 1.61% | 797 |
| chr22 | 1098622 | 2.16% | 1255 |
| chrX | 1774230 | 1.14% | 2211 |
| chrY | 73454 | 0.13% | 81 |
| 3342 contigs with no values (129077085 bp) | 0 | 0.00% | 0 |
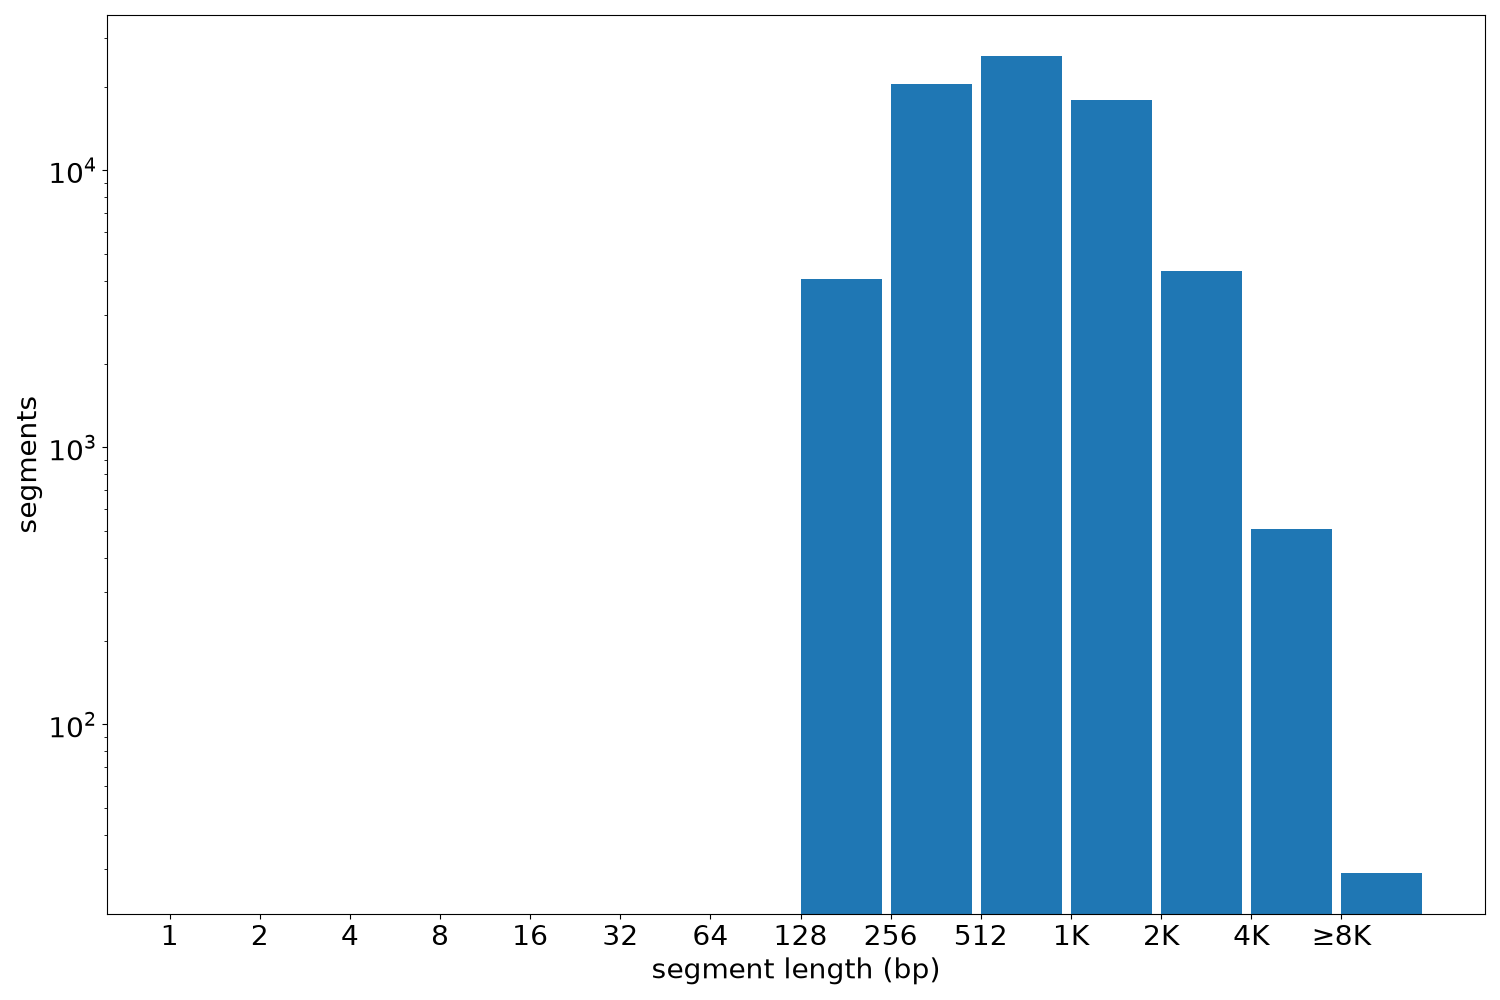
Segment lengths
| segments | min | max | mean | median | |
|---|---|---|---|---|---|
| segments | 73264 | 190 | 14427 | 918.69 | 708.5 |
Files
| Filename | Size | md5 |
|---|---|---|
| ENCFF882WZG.bed.gz | 1.75 MB | a21772e93aed0f598e6b58ac48130b5d |
| ENCFF882WZG.tabix.bed.gz | 793.45 KB | fc3fb5484a23514a96eb3ceeb3e766e6 |
| ENCFF882WZG.tabix.bed.gz.tbi | 279.01 KB | 3d52f2dea6a4b852a74e42944cdf1ffc |
| genomic_resource.yaml | 2.98 KB | e07ce00723586d79e5eee2aa52aaf085 |
| statistics/ |