Resource
| Id | DNase-seq/ENCSR866RCY |
|---|---|
| Type | position_score |
| Version | 0 |
| Summary | DNase-seq ENCSR866RCY [biosample_summary="Homo sapiens adrenal gland tissue female embryo (85 days)"] |
| Description |
status: released biological_replicates: Rep 1 summary: female embryo (85 days) output_type: peaks audit_warning: Alignment file {ENCFF284UQW|/files/ENCFF284UQW/} processed by DNase-seq ENCODE4 v3.0.0-alpha.2 GRCh38 pipeline ( {ENCPL848KLD|/pipelines/ENCPL848KLD/} ) for GRCh38 assembly has 26445848 mapped reads. According to ENCODE standards, conventional DNase-seq profile requires a minimum of 20 million uniquely mapped reads to generate a reliable SPOT (Signal Portion of Tags) score. The recommended value is > 50 million. For deep, foot-printing depth DNase-seq 150-200 million uniquely mapped reads are recommended. (See {ENCODE DNase-seq data standards|/data-standards/dnase-seq-encode4/}) audit_warning: Signal Portion of Tags (SPOT) is a measure of enrichment, analogous to the commonly used fraction of reads in peaks metric. ENCODE processed alignment files {ENCFF284UQW|/files/ENCFF284UQW/} processed by DNase-seq ENCODE4 v3.0.0-alpha.2 GRCh38 pipeline ({ENCPL848KLD|/pipelines/ENCPL848KLD/}) for GRCh38 assembly have a SPOT1 score of 0.30. According to ENCODE standards, SPOT1 score of 0.4 or higher is considered a product of high quality data. Any sample with a SPOT1 score <0.3 should be targeted for replacement with a higher quality sample, and a SPOT1 score of 0.25 is considered minimally acceptable SPOT1 score of 0.25 is considered minimally acceptable for rare and hard to find primary tissues. (See {ENCODE DNase-seq data standards|/data-standards/dnase-seq-encode4/}) |
| Labels |
|
Scores (1)
| ID | Type | Default annotation | Description | Histogram | Range | Summary |
|---|---|---|---|---|---|---|
| DNase-seq_ENCSR866RCY | float |
DNase-seq_ENCSR866RCY |
DNase-seq ENCSR866RCY [biosample_summary="Homo sapiens adrenal gland tissue female embryo (85 days)"]
|
 |
[0.304, 16] |
|
n counts base pairs; sd is the population standard deviation.
Coverage
| Chromosome | Covered positions | Covered % | Segments |
|---|---|---|---|
| all chromosomes | 7856969 | 0.24% | 46580 |
| chr1 | 714833 | 0.29% | 4219 |
| chr2 | 611873 | 0.25% | 3642 |
| chr3 | 499608 | 0.25% | 2993 |
| chr4 | 389477 | 0.20% | 2351 |
| chr5 | 423162 | 0.23% | 2556 |
| chr6 | 460628 | 0.27% | 2741 |
| chr7 | 402607 | 0.25% | 2411 |
| chr8 | 351506 | 0.24% | 2113 |
| chr9 | 322474 | 0.23% | 1927 |
| chr10 | 356807 | 0.27% | 2164 |
| chr11 | 410904 | 0.30% | 2422 |
| chr12 | 385890 | 0.29% | 2298 |
| chr13 | 213440 | 0.19% | 1267 |
| chr14 | 257463 | 0.24% | 1526 |
| chr15 | 253810 | 0.25% | 1516 |
| chr16 | 263116 | 0.29% | 1550 |
| chr17 | 324083 | 0.39% | 1882 |
| chr18 | 172464 | 0.21% | 1041 |
| chr19 | 379426 | 0.65% | 2007 |
| chr20 | 203332 | 0.32% | 1224 |
| chr21 | 91861 | 0.20% | 539 |
| chr22 | 139378 | 0.27% | 809 |
| chrX | 228667 | 0.15% | 1381 |
| chrY | 160 | <0.01% | 1 |
| 3342 contigs with no values (129077085 bp) | 0 | 0.00% | 0 |
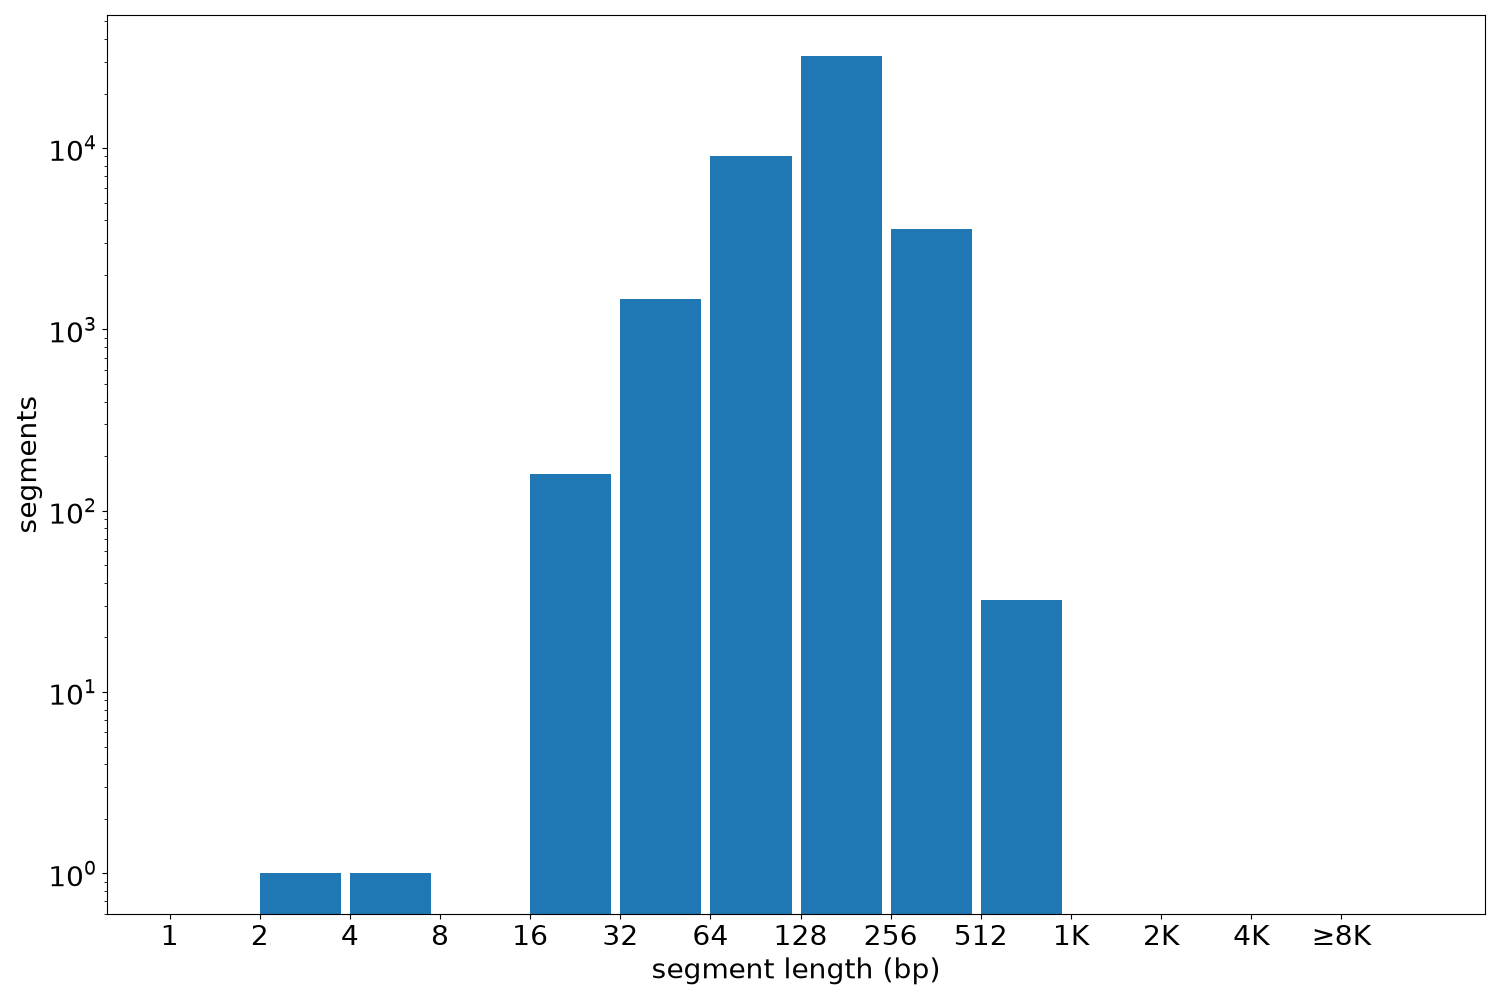
Segment lengths
| segments | min | max | mean | median | |
|---|---|---|---|---|---|
| segments | 46580 | 3 | 680 | 168.68 | 160 |
Files
| Filename | Size | md5 |
|---|---|---|
| ENCFF522YCT.bed.gz | 490.75 KB | 7fb9f4cb48e381569f16e4d53e3a34dc |
| ENCFF522YCT.tabix.bed.gz | 433.37 KB | 0097b4d393ee2dc5ce9481c33d5af764 |
| ENCFF522YCT.tabix.bed.gz.tbi | 288.61 KB | 9b154f3dd33b6f196415d00a61fbc4a4 |
| genomic_resource.yaml | 2.67 KB | 324b6a38a3202cd59acee8f515a3a3e0 |
| statistics/ |