Resource
| Id | DNase-seq/ENCSR746ZPP |
|---|---|
| Type | position_score |
| Version | 0 |
| Summary | DNase-seq ENCSR746ZPP [biosample_summary="Homo sapiens L1-S8R"] |
| Description |
status: released biological_replicates: Rep 1 summary: output_type: peaks audit_warning: Signal Portion of Tags (SPOT) is a measure of enrichment, analogous to the commonly used fraction of reads in peaks metric. ENCODE processed alignment files {ENCFF526RIQ|/files/ENCFF526RIQ/} processed by DNase-seq ENCODE4 v3.0.0-alpha.2 GRCh38 pipeline ({ENCPL848KLD|/pipelines/ENCPL848KLD/}) for GRCh38 assembly have a SPOT1 score of 0.25. According to ENCODE standards, SPOT1 score of 0.4 or higher is considered a product of high quality data. Any sample with a SPOT1 score <0.3 should be targeted for replacement with a higher quality sample, and a SPOT1 score of 0.25 is considered minimally acceptable SPOT1 score of 0.25 is considered minimally acceptable for rare and hard to find primary tissues. (See {ENCODE DNase-seq data standards|/data-standards/dnase-seq-encode4/}) audit_warning: Signal Portion of Tags (SPOT) is a measure of enrichment, analogous to the commonly used fraction of reads in peaks metric. ENCODE processed alignment files {ENCFF414ZYF|/files/ENCFF414ZYF/} processed by DNase-seq ENCODE4 v3.0.0-alpha.2 GRCh38 pipeline ({ENCPL848KLD|/pipelines/ENCPL848KLD/}) for GRCh38 assembly have a SPOT1 score of 0.25. According to ENCODE standards, SPOT1 score of 0.4 or higher is considered a product of high quality data. Any sample with a SPOT1 score <0.3 should be targeted for replacement with a higher quality sample, and a SPOT1 score of 0.25 is considered minimally acceptable SPOT1 score of 0.25 is considered minimally acceptable for rare and hard to find primary tissues. (See {ENCODE DNase-seq data standards|/data-standards/dnase-seq-encode4/}) |
| Labels |
|
Scores (1)
| ID | Type | Default annotation | Description | Histogram | Range | Summary |
|---|---|---|---|---|---|---|
| DNase-seq_ENCSR746ZPP | float |
DNase-seq_ENCSR746ZPP |
DNase-seq ENCSR746ZPP [biosample_summary="Homo sapiens L1-S8R"]
|
 |
[0.0229, 12.9] |
|
n counts base pairs; sd is the population standard deviation.
Coverage
| Chromosome | Covered positions | Covered % | Segments |
|---|---|---|---|
| all chromosomes | 33211350 | 1.03% | 158413 |
| chr1 | 2932826 | 1.18% | 13913 |
| chr2 | 2697462 | 1.11% | 12803 |
| chr3 | 2258444 | 1.14% | 10709 |
| chr4 | 1797669 | 0.95% | 8584 |
| chr5 | 1866283 | 1.03% | 8915 |
| chr6 | 2005707 | 1.17% | 9441 |
| chr7 | 1670371 | 1.05% | 7969 |
| chr8 | 1559716 | 1.07% | 7467 |
| chr9 | 1372676 | 0.99% | 6554 |
| chr10 | 1546095 | 1.16% | 7375 |
| chr11 | 1647981 | 1.22% | 7896 |
| chr12 | 1614609 | 1.21% | 7659 |
| chr13 | 950319 | 0.83% | 4568 |
| chr14 | 1067016 | 1.00% | 5093 |
| chr15 | 1046728 | 1.03% | 4992 |
| chr16 | 1070371 | 1.18% | 5155 |
| chr17 | 1313997 | 1.58% | 6252 |
| chr18 | 802105 | 1.00% | 3879 |
| chr19 | 968306 | 1.65% | 4576 |
| chr20 | 837844 | 1.30% | 4013 |
| chr21 | 354822 | 0.76% | 1713 |
| chr22 | 568120 | 1.12% | 2736 |
| chrX | 1190992 | 0.76% | 5770 |
| chrY | 70891 | 0.12% | 381 |
| 3342 contigs with no values (129077085 bp) | 0 | 0.00% | 0 |
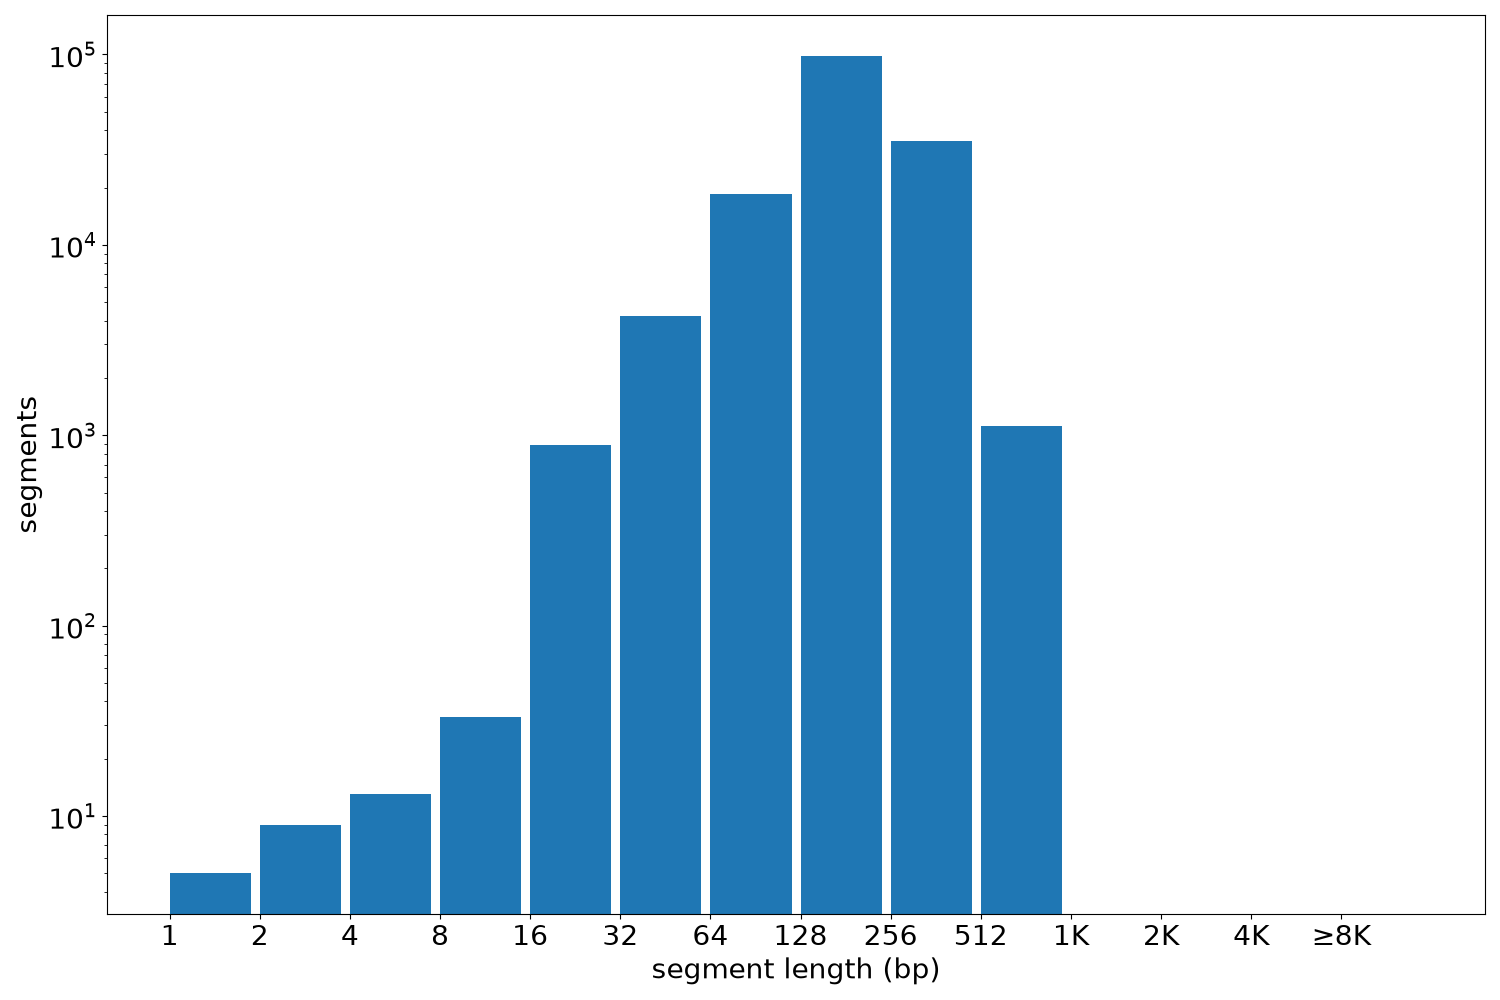
Segment lengths
| segments | min | max | mean | median | |
|---|---|---|---|---|---|
| segments | 158413 | 1 | 947 | 209.65 | 200 |
Files
| Filename | Size | md5 |
|---|---|---|
| ENCFF783XJK.bed.gz | 1.69 MB | 3eb205ceb23b58a8e08dfc9dd868153d |
| ENCFF783XJK.tabix.bed.gz | 1.55 MB | 6c84d2f3638ffb28a7526ff6a3cf059a |
| ENCFF783XJK.tabix.bed.gz.tbi | 598.6 KB | 7436546867696eabd7e43c7117707f4a |
| genomic_resource.yaml | 2.77 KB | 49f2e985ffd30208c0d4e648f39a7d71 |
| statistics/ |