Resource
| Id | DNase-seq/ENCSR642DZF |
|---|---|
| Type | position_score |
| Version | 0 |
| Summary | DNase-seq ENCSR642DZF [biosample_summary="Homo sapiens T-cell female adult (33 years)"] |
| Description |
status: released biological_replicates: Rep 1 summary: female adult (33 years) output_type: peaks audit_internal_action: Released analysis {ENCAN445JVT|/analyses/ENCAN445JVT/} has in progress subobject document {e0a2fa89-7952-4313-8a5f-ce81138c32e6|/documents/e0a2fa89-7952-4313-8a5f-ce81138c32e6/} audit_internal_action: Released analysis {ENCAN445JVT|/analyses/ENCAN445JVT/} has in progress subobject document {b716a2b7-45e2-454c-ab37-2c1ce0e725db|/documents/b716a2b7-45e2-454c-ab37-2c1ce0e725db/} audit_warning: Alignment file {ENCFF608NVR|/files/ENCFF608NVR/} processed by DNase-seq ENCODE4 v3.0.0-alpha.2 GRCh38 pipeline ( {ENCPL848KLD|/pipelines/ENCPL848KLD/} ) for GRCh38 assembly has 39470022 mapped reads. According to ENCODE standards, conventional DNase-seq profile requires a minimum of 20 million uniquely mapped reads to generate a reliable SPOT (Signal Portion of Tags) score. The recommended value is > 50 million. For deep, foot-printing depth DNase-seq 150-200 million uniquely mapped reads are recommended. (See {ENCODE DNase-seq data standards|/data-standards/dnase-seq-encode4/}) |
| Labels |
|
Scores (1)
| ID | Type | Default annotation | Description | Histogram | Range | Summary |
|---|---|---|---|---|---|---|
| DNase-seq_ENCSR642DZF | float |
DNase-seq_ENCSR642DZF |
DNase-seq ENCSR642DZF [biosample_summary="Homo sapiens T-cell female adult (33 years)"]
|
 |
[0.229, 161] |
|
n counts base pairs; sd is the population standard deviation.
Coverage
| Chromosome | Covered positions | Covered % | Segments |
|---|---|---|---|
| all chromosomes | 8013579 | 0.25% | 44120 |
| chr1 | 806696 | 0.32% | 4419 |
| chr2 | 567242 | 0.23% | 3145 |
| chr3 | 434557 | 0.22% | 2408 |
| chr4 | 273599 | 0.14% | 1507 |
| chr5 | 362677 | 0.20% | 1999 |
| chr6 | 469661 | 0.27% | 2585 |
| chr7 | 376377 | 0.24% | 2078 |
| chr8 | 292964 | 0.20% | 1617 |
| chr9 | 310846 | 0.22% | 1715 |
| chr10 | 354581 | 0.27% | 1967 |
| chr11 | 406198 | 0.30% | 2243 |
| chr12 | 410495 | 0.31% | 2271 |
| chr13 | 161304 | 0.14% | 883 |
| chr14 | 281596 | 0.26% | 1564 |
| chr15 | 256648 | 0.25% | 1448 |
| chr16 | 327904 | 0.36% | 1794 |
| chr17 | 503722 | 0.61% | 2751 |
| chr18 | 124972 | 0.16% | 706 |
| chr19 | 532039 | 0.91% | 2835 |
| chr20 | 224248 | 0.35% | 1254 |
| chr21 | 100930 | 0.22% | 542 |
| chr22 | 189812 | 0.37% | 1051 |
| chrX | 244511 | 0.16% | 1338 |
| 3343 contigs with no values (186304500 bp) | 0 | 0.00% | 0 |
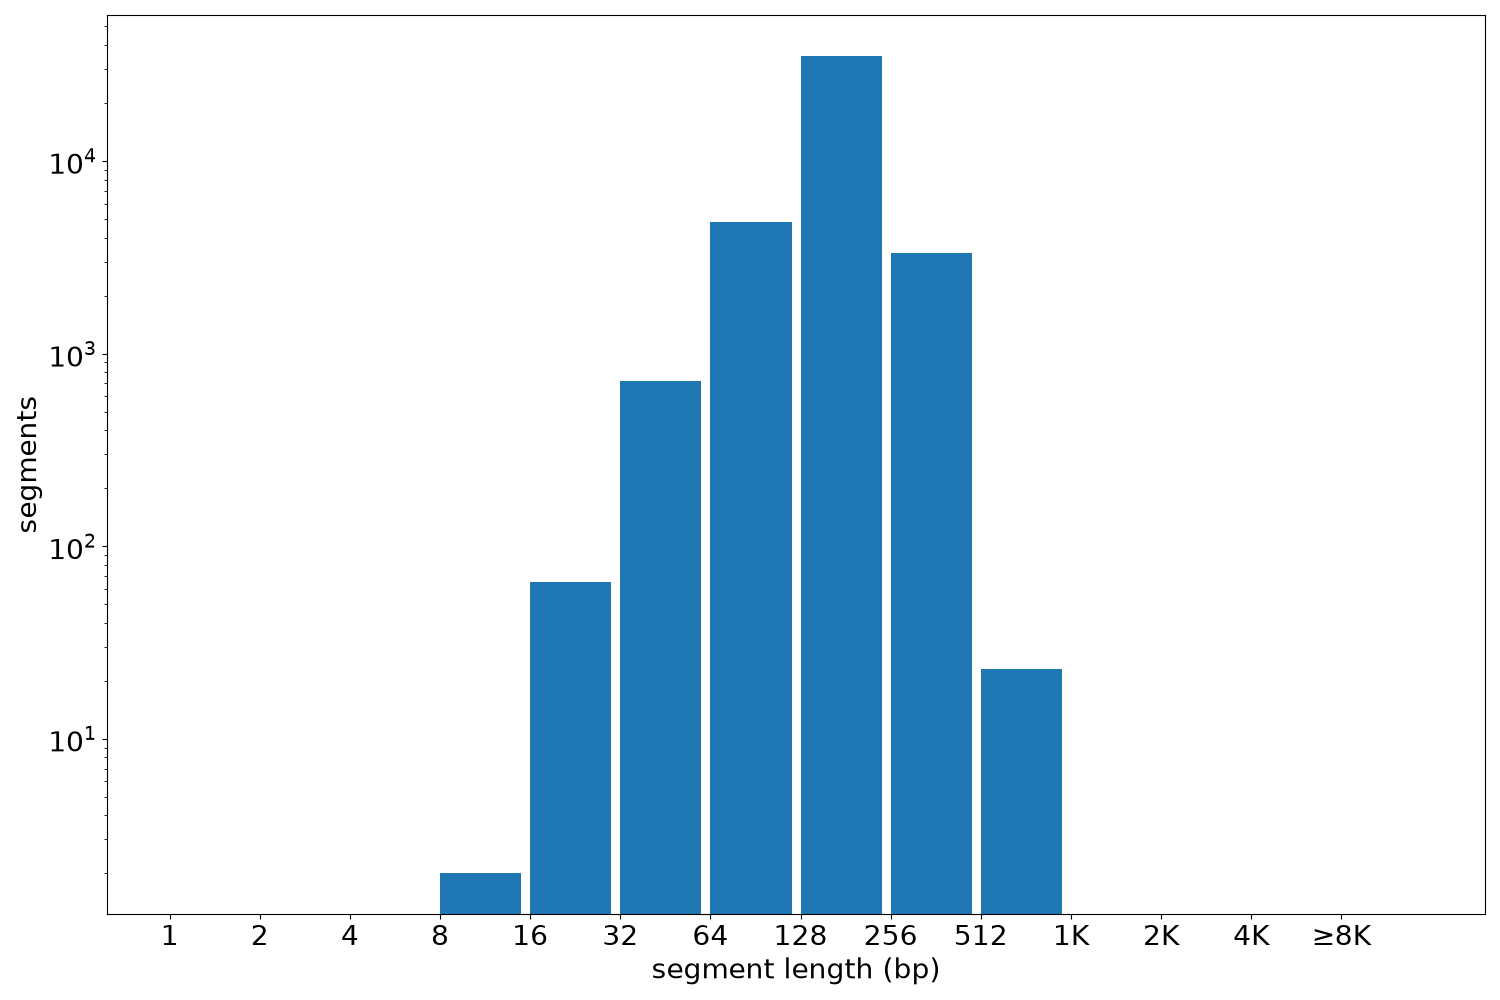
Segment lengths
| segments | min | max | mean | median | |
|---|---|---|---|---|---|
| segments | 44120 | 8 | 720 | 181.63 | 180 |
Files
| Filename | Size | md5 |
|---|---|---|
| ENCFF060XOT.bed.gz | 495.26 KB | cf4e114da91ec41c46d31f0b76be58a9 |
| ENCFF060XOT.tabix.bed.gz | 447.86 KB | b6cb82f7d9a342f7a54e36b555619685 |
| ENCFF060XOT.tabix.bed.gz.tbi | 218.4 KB | 31e112e8c96744bbe874fd05f1d08c0a |
| genomic_resource.yaml | 2.23 KB | ab64ec0ffca300e823200564eb2d7339 |
| statistics/ |