Resource
| Id | DNase-seq/ENCSR000EPP |
|---|---|
| Type | position_score |
| Version | 0 |
| Summary | DNase-seq ENCSR000EPP [biosample_summary="Homo sapiens foreskin fibroblast male newborn"] |
| Description |
status: released biological_replicates: Rep 1 summary: male newborn output_type: peaks audit_internal_action: Archived analysis {ENCAN098BOO|/analyses/ENCAN098BOO/} has in progress subobject quality standard {encode3-dnase|/quality-standards/encode3-dnase/} audit_warning: Alignment file {ENCFF732BYR|/files/ENCFF732BYR/} processed by DNase-seq ENCODE3 GRCh38 pipeline ( {ENCPL001DNS|/pipelines/ENCPL001DNS/} ) for GRCh38 assembly has 38942186 mapped reads. According to ENCODE standards, conventional DNase-seq profile requires a minimum of 20 million uniquely mapped reads to generate a reliable SPOT (Signal Portion of Tags) score. The recommended value is > 50 million. For deep, foot-printing depth DNase-seq 150-200 million uniquely mapped reads are recommended. (See {ENCODE DNase-seq data standards|/data-standards/dnase-seq/}) |
| Labels |
|
Scores (1)
| ID | Type | Default annotation | Description | Histogram | Range | Summary |
|---|---|---|---|---|---|---|
| DNase-seq_ENCSR000EPP | float |
DNase-seq_ENCSR000EPP |
DNase-seq ENCSR000EPP [biosample_summary="Homo sapiens foreskin fibroblast male newborn"]
|
 |
[6, 2.01e+05] |
|
n counts base pairs; sd is the population standard deviation.
Coverage
| Chromosome | Covered positions | Covered % | Segments |
|---|---|---|---|
| all chromosomes | 54774952 | 1.70% | 364887 |
| chr1 | 4930003 | 1.98% | 32834 |
| chr2 | 4683623 | 1.93% | 31203 |
| chr3 | 3818998 | 1.93% | 25444 |
| chr4 | 3022285 | 1.59% | 20136 |
| chr5 | 3334127 | 1.84% | 22207 |
| chr6 | 3498323 | 2.05% | 23311 |
| chr7 | 2801746 | 1.76% | 18663 |
| chr8 | 2704523 | 1.86% | 18014 |
| chr9 | 2379445 | 1.72% | 15852 |
| chr10 | 2665300 | 1.99% | 17757 |
| chr11 | 2560014 | 1.90% | 17052 |
| chr12 | 2724472 | 2.04% | 18147 |
| chr13 | 1634747 | 1.43% | 10885 |
| chr14 | 1675295 | 1.57% | 11161 |
| chr15 | 1755676 | 1.72% | 11699 |
| chr16 | 1523391 | 1.69% | 10152 |
| chr17 | 1987006 | 2.39% | 13242 |
| chr18 | 1320771 | 1.64% | 8798 |
| chr19 | 1234972 | 2.11% | 8227 |
| chr20 | 1321299 | 2.05% | 8803 |
| chr21 | 674550 | 1.44% | 4494 |
| chr22 | 799719 | 1.57% | 5331 |
| chrX | 1627767 | 1.04% | 10829 |
| chrY | 96900 | 0.17% | 646 |
| 3342 contigs with no values (129077085 bp) | 0 | 0.00% | 0 |
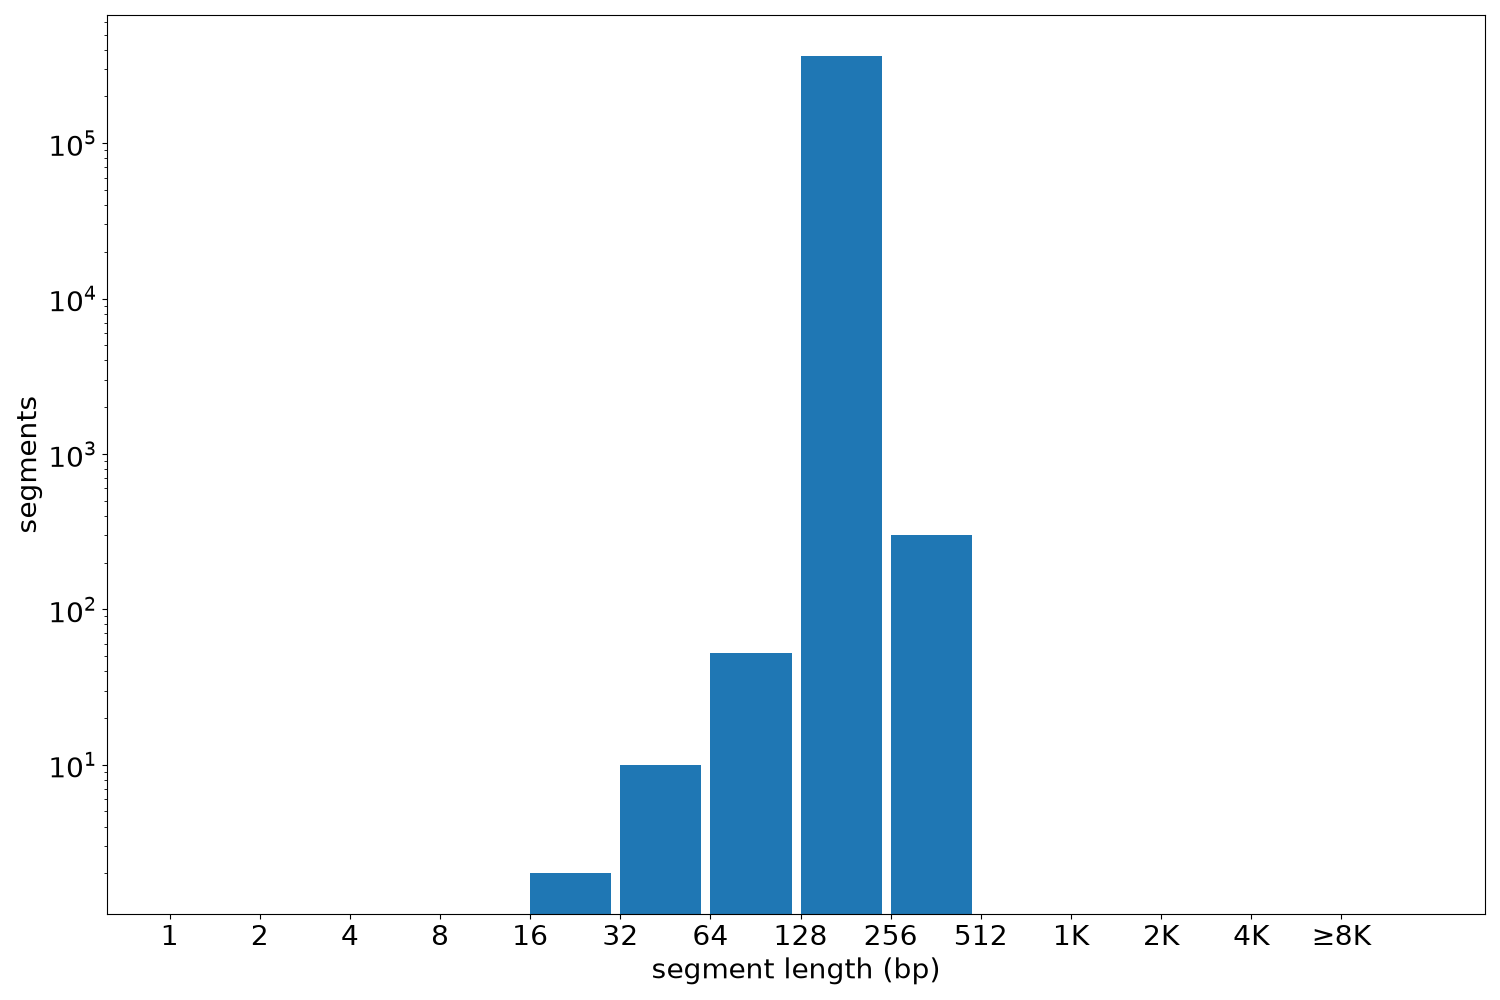
Segment lengths
| segments | min | max | mean | median | |
|---|---|---|---|---|---|
| segments | 364887 | 23 | 450 | 150.11 | 150 |
Files
| Filename | Size | md5 |
|---|---|---|
| ENCFF674URJ.bed.gz | 3.46 MB | 29b91108fb4546a18edf937436f60171 |
| ENCFF674URJ.tabix.bed.gz | 3.0 MB | 022dfe7322e890300b42c13cc5a0aaf1 |
| ENCFF674URJ.tabix.bed.gz.tbi | 819.19 KB | 5eafa0279e5c83f76f05aaef174ce31b |
| genomic_resource.yaml | 1.94 KB | 0b223587a984140000b52d182322c60d |
| statistics/ |