Resource
| Id | DNase-seq/ENCSR000ENG |
|---|---|
| Type | position_score |
| Version | 0 |
| Summary | DNase-seq ENCSR000ENG [biosample_summary="Homo sapiens smooth muscle cell of the brain vasculature female"] |
| Description |
status: released biological_replicates: Rep 1 summary: female output_type: peaks audit_internal_action: Archived analysis {ENCAN504LSO|/analyses/ENCAN504LSO/} has in progress subobject quality standard {encode3-dnase|/quality-standards/encode3-dnase/} audit_warning: Alignment file {ENCFF369LCZ|/files/ENCFF369LCZ/} processed by DNase-seq ENCODE3 GRCh38 pipeline ( {ENCPL001DNS|/pipelines/ENCPL001DNS/} ) for GRCh38 assembly has 26642568 mapped reads. According to ENCODE standards, conventional DNase-seq profile requires a minimum of 20 million uniquely mapped reads to generate a reliable SPOT (Signal Portion of Tags) score. The recommended value is > 50 million. For deep, foot-printing depth DNase-seq 150-200 million uniquely mapped reads are recommended. (See {ENCODE DNase-seq data standards|/data-standards/dnase-seq/}) audit_warning: Alignment file {ENCFF295AFC|/files/ENCFF295AFC/} processed by DNase-seq ENCODE3 GRCh38 pipeline ( {ENCPL001DNS|/pipelines/ENCPL001DNS/} ) for GRCh38 assembly has 26183348 mapped reads. According to ENCODE standards, conventional DNase-seq profile requires a minimum of 20 million uniquely mapped reads to generate a reliable SPOT (Signal Portion of Tags) score. The recommended value is > 50 million. For deep, foot-printing depth DNase-seq 150-200 million uniquely mapped reads are recommended. (See {ENCODE DNase-seq data standards|/data-standards/dnase-seq/}) audit_warning: Alignment file {ENCFF557GXL|/files/ENCFF557GXL/} processed by DNase-seq ENCODE3 GRCh38 pipeline ( {ENCPL001DNS|/pipelines/ENCPL001DNS/} ) for GRCh38 assembly has 26470388 mapped reads. According to ENCODE standards, conventional DNase-seq profile requires a minimum of 20 million uniquely mapped reads to generate a reliable SPOT (Signal Portion of Tags) score. The recommended value is > 50 million. For deep, foot-printing depth DNase-seq 150-200 million uniquely mapped reads are recommended. (See {ENCODE DNase-seq data standards|/data-standards/dnase-seq/}) audit_warning: Alignment file {ENCFF994IJJ|/files/ENCFF994IJJ/} processed by DNase-seq ENCODE3 GRCh38 pipeline ( {ENCPL001DNS|/pipelines/ENCPL001DNS/} ) for GRCh38 assembly has 25993458 mapped reads. According to ENCODE standards, conventional DNase-seq profile requires a minimum of 20 million uniquely mapped reads to generate a reliable SPOT (Signal Portion of Tags) score. The recommended value is > 50 million. For deep, foot-printing depth DNase-seq 150-200 million uniquely mapped reads are recommended. (See {ENCODE DNase-seq data standards|/data-standards/dnase-seq/}) audit_warning: Signal Portion of Tags (SPOT) is a measure of enrichment, analogous to the commonly used fraction of reads in peaks metric. ENCODE processed alignment files {ENCFF557GXL|/files/ENCFF557GXL/} processed by DNase-seq ENCODE3 GRCh38 pipeline ({ENCPL001DNS|/pipelines/ENCPL001DNS/}) for GRCh38 assembly have a SPOT1 score of 0.40. According to ENCODE standards, SPOT1 score of 0.4 or higher is considered a product of high quality data. Any sample with a SPOT1 score <0.3 should be targeted for replacement with a higher quality sample, and a SPOT1 score of 0.25 is considered minimally acceptable SPOT1 score of 0.25 is considered minimally acceptable for rare and hard to find primary tissues. (See {ENCODE DNase-seq data standards|/data-standards/dnase-seq/}) |
| Labels |
|
Scores (1)
| ID | Type | Default annotation | Description | Histogram | Range | Summary |
|---|---|---|---|---|---|---|
| DNase-seq_ENCSR000ENG | float |
DNase-seq_ENCSR000ENG |
DNase-seq ENCSR000ENG [biosample_summary="Homo sapiens smooth muscle cell of the brain vasculature female"]
|
 |
[3, 7.51e+03] |
|
n counts base pairs; sd is the population standard deviation.
Coverage
| Chromosome | Covered positions | Covered % | Segments |
|---|---|---|---|
| all chromosomes | 10421830 | 0.32% | 69244 |
| chr1 | 943184 | 0.38% | 6273 |
| chr2 | 854939 | 0.35% | 5677 |
| chr3 | 719176 | 0.36% | 4779 |
| chr4 | 566762 | 0.30% | 3754 |
| chr5 | 607953 | 0.33% | 4034 |
| chr6 | 673765 | 0.39% | 4474 |
| chr7 | 543296 | 0.34% | 3610 |
| chr8 | 476102 | 0.33% | 3160 |
| chr9 | 434017 | 0.31% | 2889 |
| chr10 | 484448 | 0.36% | 3214 |
| chr11 | 514371 | 0.38% | 3419 |
| chr12 | 524156 | 0.39% | 3489 |
| chr13 | 311003 | 0.27% | 2067 |
| chr14 | 322304 | 0.30% | 2139 |
| chr15 | 339474 | 0.33% | 2255 |
| chr16 | 312253 | 0.35% | 2076 |
| chr17 | 406727 | 0.49% | 2707 |
| chr18 | 234409 | 0.29% | 1557 |
| chr19 | 343433 | 0.59% | 2284 |
| chr20 | 257105 | 0.40% | 1710 |
| chr21 | 122850 | 0.26% | 816 |
| chr22 | 166115 | 0.33% | 1106 |
| chrX | 263538 | 0.17% | 1752 |
| chrY | 450 | <0.01% | 3 |
| 3342 contigs with no values (129077085 bp) | 0 | 0.00% | 0 |
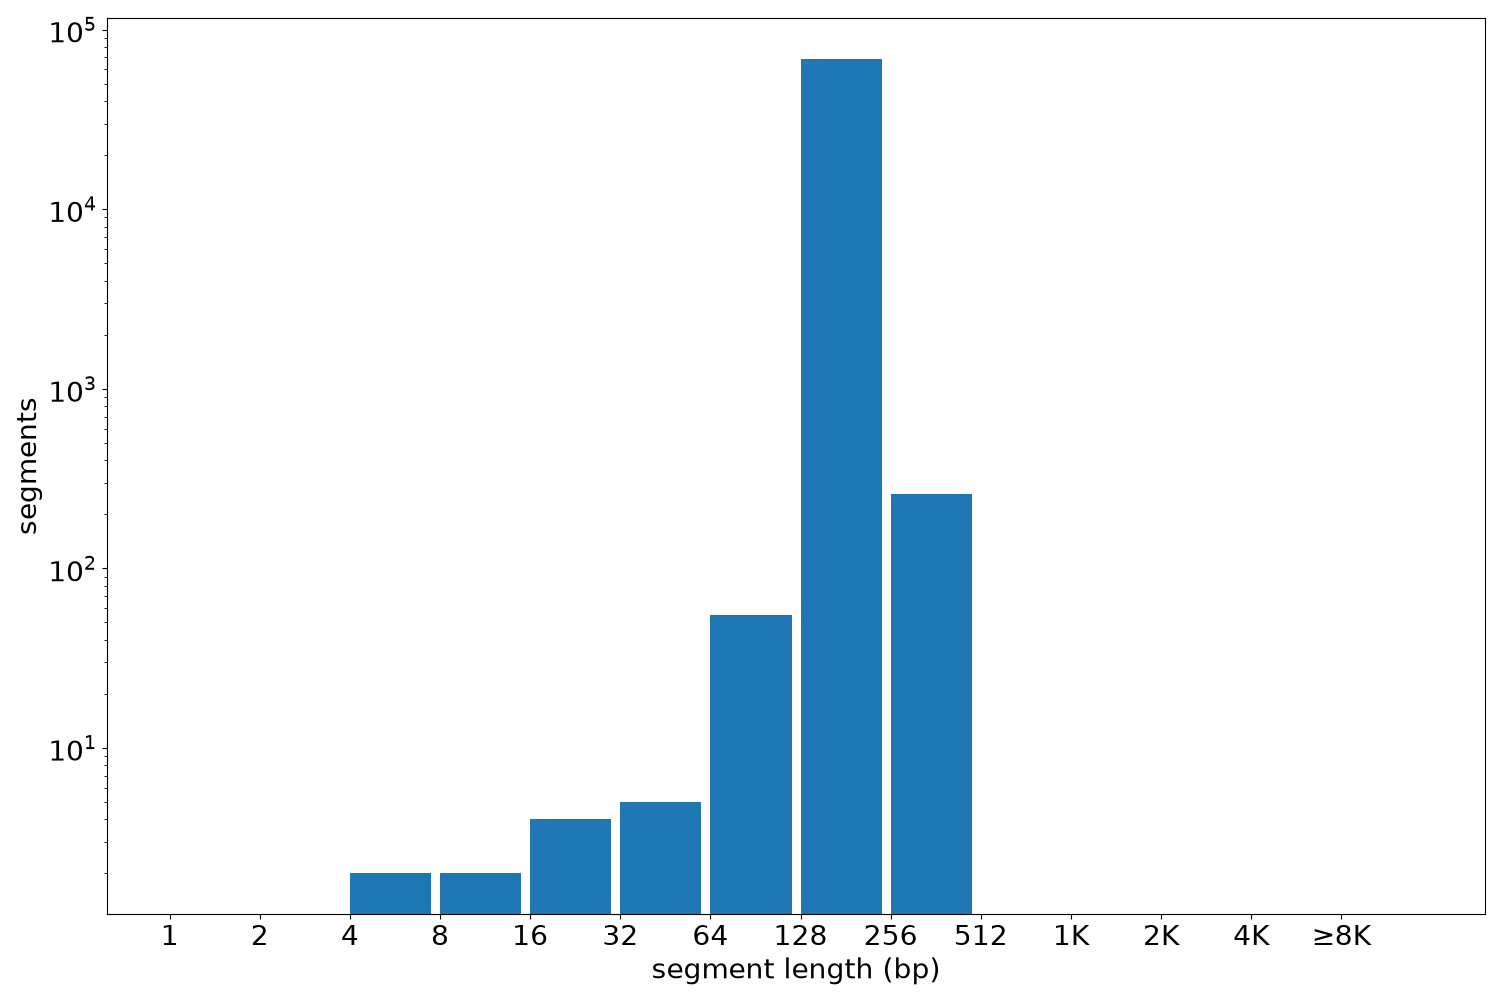
Segment lengths
| segments | min | max | mean | median | |
|---|---|---|---|---|---|
| segments | 69244 | 5 | 450 | 150.51 | 150 |
Files
| Filename | Size | md5 |
|---|---|---|
| ENCFF291PDD.bed.gz | 673.15 KB | d4bfce73b8d41990b2432b9d70917fcc |
| ENCFF291PDD.tabix.bed.gz | 577.27 KB | 1a66e1e86e1ccdbf0e0ac0e4a6192a5a |
| ENCFF291PDD.tabix.bed.gz.tbi | 373.04 KB | 7d67234052d1709c83d91a8c964ee5ba |
| genomic_resource.yaml | 4.58 KB | 6a509c26523a525a00950810401493eb |
| statistics/ |