Resource
| Id | DNase-seq/ENCSR000ENC |
|---|---|
| Type | position_score |
| Version | 0 |
| Summary | DNase-seq ENCSR000ENC [biosample_summary="Homo sapiens astrocyte of the cerebellum"] |
| Description |
status: released biological_replicates: Rep 1 summary: output_type: peaks audit_warning: Alignment file {ENCFF510MDM|/files/ENCFF510MDM/} processed by DNase-seq ENCODE4 v3.0.0-alpha.2 GRCh38 pipeline ( {ENCPL848KLD|/pipelines/ENCPL848KLD/} ) for GRCh38 assembly has 39982004 mapped reads. According to ENCODE standards, conventional DNase-seq profile requires a minimum of 20 million uniquely mapped reads to generate a reliable SPOT (Signal Portion of Tags) score. The recommended value is > 50 million. For deep, foot-printing depth DNase-seq 150-200 million uniquely mapped reads are recommended. (See {ENCODE DNase-seq data standards|/data-standards/dnase-seq-encode4/}) audit_warning: Alignment file {ENCFF561FMQ|/files/ENCFF561FMQ/} processed by DNase-seq ENCODE4 v3.0.0-alpha.2 GRCh38 pipeline ( {ENCPL848KLD|/pipelines/ENCPL848KLD/} ) for GRCh38 assembly has 28365054 mapped reads. According to ENCODE standards, conventional DNase-seq profile requires a minimum of 20 million uniquely mapped reads to generate a reliable SPOT (Signal Portion of Tags) score. The recommended value is > 50 million. For deep, foot-printing depth DNase-seq 150-200 million uniquely mapped reads are recommended. (See {ENCODE DNase-seq data standards|/data-standards/dnase-seq-encode4/}) |
| Labels |
|
Scores (1)
| ID | Type | Default annotation | Description | Histogram | Range | Summary |
|---|---|---|---|---|---|---|
| DNase-seq_ENCSR000ENC | float |
DNase-seq_ENCSR000ENC |
DNase-seq ENCSR000ENC [biosample_summary="Homo sapiens astrocyte of the cerebellum"]
|
 |
[0.176, 23.5] |
|
n counts base pairs; sd is the population standard deviation.
Coverage
| Chromosome | Covered positions | Covered % | Segments |
|---|---|---|---|
| all chromosomes | 17776575 | 0.55% | 100238 |
| chr1 | 1590849 | 0.64% | 8952 |
| chr2 | 1519037 | 0.63% | 8551 |
| chr3 | 1261601 | 0.64% | 7100 |
| chr4 | 1020324 | 0.54% | 5834 |
| chr5 | 1083554 | 0.60% | 6121 |
| chr6 | 1125550 | 0.66% | 6306 |
| chr7 | 927232 | 0.58% | 5235 |
| chr8 | 836449 | 0.58% | 4740 |
| chr9 | 748650 | 0.54% | 4221 |
| chr10 | 832699 | 0.62% | 4700 |
| chr11 | 870316 | 0.64% | 4933 |
| chr12 | 860984 | 0.65% | 4864 |
| chr13 | 551793 | 0.48% | 3109 |
| chr14 | 561386 | 0.52% | 3161 |
| chr15 | 559537 | 0.55% | 3129 |
| chr16 | 519574 | 0.58% | 2919 |
| chr17 | 644783 | 0.77% | 3621 |
| chr18 | 434482 | 0.54% | 2508 |
| chr19 | 477731 | 0.81% | 2579 |
| chr20 | 397933 | 0.62% | 2237 |
| chr21 | 215775 | 0.46% | 1210 |
| chr22 | 256192 | 0.50% | 1455 |
| chrX | 479602 | 0.31% | 2749 |
| chrY | 542 | <0.01% | 4 |
| 3342 contigs with no values (129077085 bp) | 0 | 0.00% | 0 |
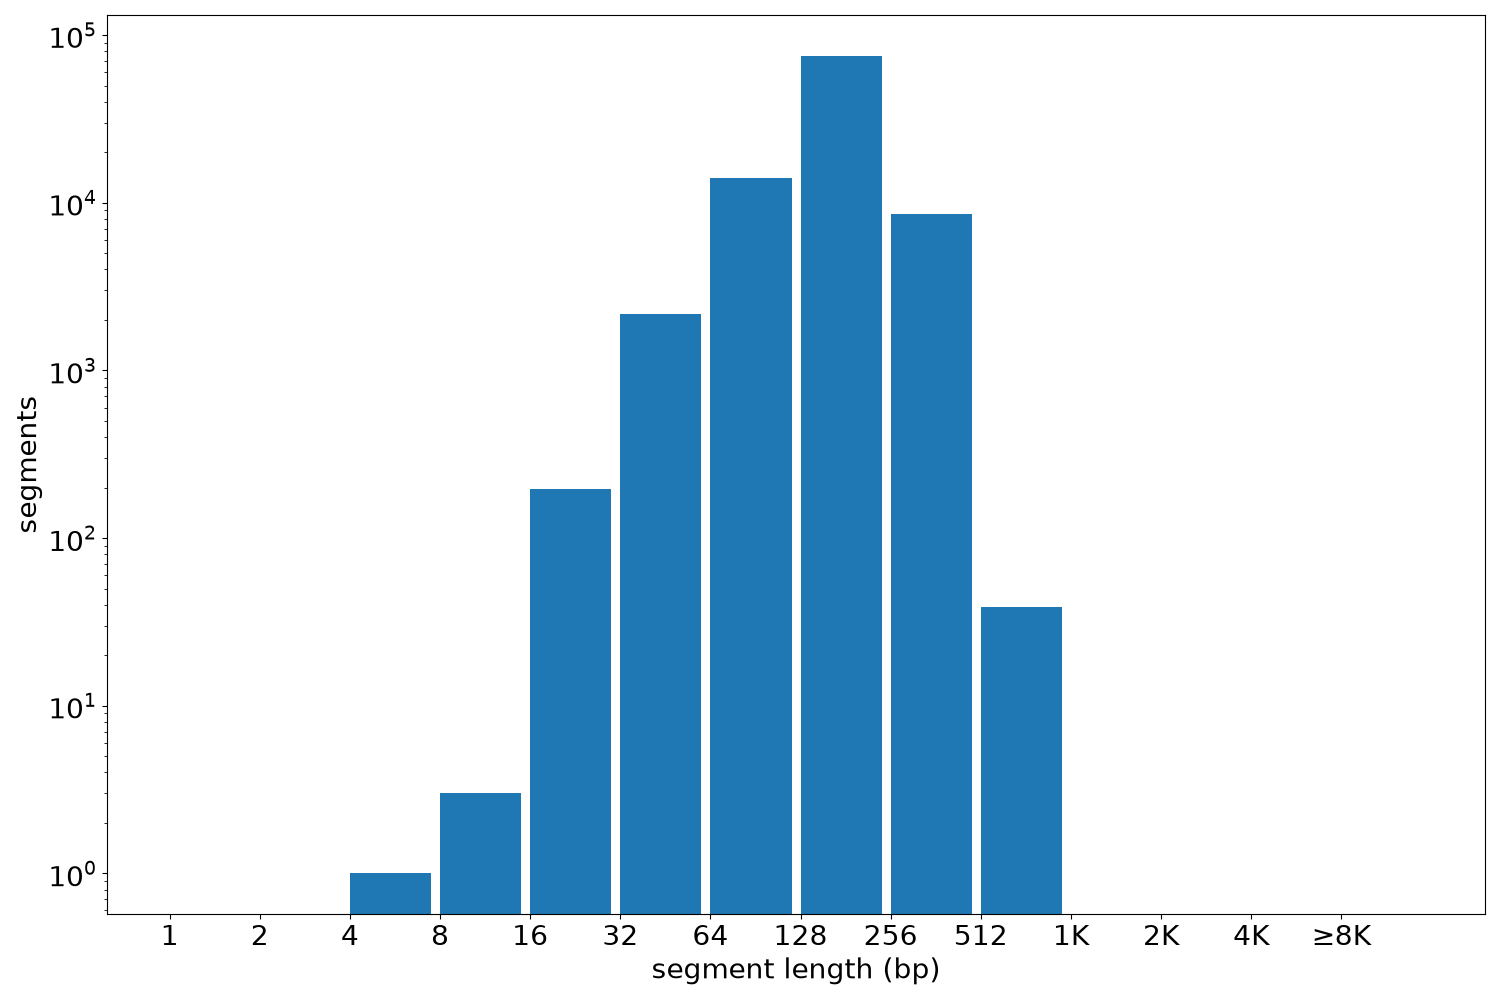
Segment lengths
| segments | min | max | mean | median | |
|---|---|---|---|---|---|
| segments | 100238 | 5 | 740 | 177.34 | 180 |
Files
| Filename | Size | md5 |
|---|---|---|
| ENCFF036TMU.bed.gz | 1.03 MB | 5414d96bc0a4d9697d58906acee98b0d |
| ENCFF036TMU.tabix.bed.gz | 950.95 KB | 22adf4c749c4294b7229effe11179994 |
| ENCFF036TMU.tabix.bed.gz.tbi | 484.8 KB | 9264b4e47d28f41bda914f14e363080e |
| genomic_resource.yaml | 2.41 KB | 8a4071dda921de1a744b38f55efbedd6 |
| statistics/ |