Resource
| Id | DNase-seq/ENCSR000EJT |
|---|---|
| Type | position_score |
| Version | 0 |
| Summary | DNase-seq ENCSR000EJT [biosample_summary="Homo sapiens HeLa-S3"] |
| Description |
status: released biological_replicates: Rep 1 summary: output_type: peaks audit_internal_action: Archived analysis {ENCAN618JRK|/analyses/ENCAN618JRK/} has in progress subobject quality standard {encode3-dnase|/quality-standards/encode3-dnase/} audit_warning: Alignment file {ENCFF342EWC|/files/ENCFF342EWC/} processed by DNase-seq ENCODE3 GRCh38 pipeline ( {ENCPL001DNS|/pipelines/ENCPL001DNS/} ) for GRCh38 assembly has 48557781 mapped reads. According to ENCODE standards, conventional DNase-seq profile requires a minimum of 20 million uniquely mapped reads to generate a reliable SPOT (Signal Portion of Tags) score. The recommended value is > 50 million. For deep, foot-printing depth DNase-seq 150-200 million uniquely mapped reads are recommended. (See {ENCODE DNase-seq data standards|/data-standards/dnase-seq/}) audit_warning: Signal Portion of Tags (SPOT) is a measure of enrichment, analogous to the commonly used fraction of reads in peaks metric. ENCODE processed alignment files {ENCFF342EWC|/files/ENCFF342EWC/} processed by DNase-seq ENCODE3 GRCh38 pipeline ({ENCPL001DNS|/pipelines/ENCPL001DNS/}) for GRCh38 assembly have a SPOT1 score of 0.40. According to ENCODE standards, SPOT1 score of 0.4 or higher is considered a product of high quality data. Any sample with a SPOT1 score <0.3 should be targeted for replacement with a higher quality sample, and a SPOT1 score of 0.25 is considered minimally acceptable SPOT1 score of 0.25 is considered minimally acceptable for rare and hard to find primary tissues. (See {ENCODE DNase-seq data standards|/data-standards/dnase-seq/}) |
| Labels |
|
Scores (1)
| ID | Type | Default annotation | Description | Histogram | Range | Summary |
|---|---|---|---|---|---|---|
| DNase-seq_ENCSR000EJT | float |
DNase-seq_ENCSR000EJT |
DNase-seq ENCSR000EJT [biosample_summary="Homo sapiens HeLa-S3"]
|
 |
[3, 736] |
|
n counts base pairs; sd is the population standard deviation.
Coverage
| Chromosome | Covered positions | Covered % | Segments |
|---|---|---|---|
| all chromosomes | 14319622 | 0.45% | 95287 |
| chr1 | 1378446 | 0.55% | 9179 |
| chr2 | 976463 | 0.40% | 6504 |
| chr3 | 843963 | 0.43% | 5615 |
| chr4 | 520350 | 0.27% | 3457 |
| chr5 | 785670 | 0.43% | 5233 |
| chr6 | 779521 | 0.46% | 5185 |
| chr7 | 690688 | 0.43% | 4596 |
| chr8 | 633263 | 0.44% | 4214 |
| chr9 | 831018 | 0.60% | 5522 |
| chr10 | 629395 | 0.47% | 4193 |
| chr11 | 779234 | 0.58% | 5183 |
| chr12 | 722257 | 0.54% | 4804 |
| chr13 | 293379 | 0.26% | 1952 |
| chr14 | 461544 | 0.43% | 3073 |
| chr15 | 500251 | 0.49% | 3331 |
| chr16 | 547063 | 0.61% | 3640 |
| chr17 | 729485 | 0.88% | 4859 |
| chr18 | 303382 | 0.38% | 2019 |
| chr19 | 661803 | 1.13% | 4402 |
| chr20 | 403703 | 0.63% | 2679 |
| chr21 | 160737 | 0.34% | 1072 |
| chr22 | 260061 | 0.51% | 1730 |
| chrX | 427796 | 0.27% | 2844 |
| chrY | 150 | <0.01% | 1 |
| 3342 contigs with no values (129077085 bp) | 0 | 0.00% | 0 |
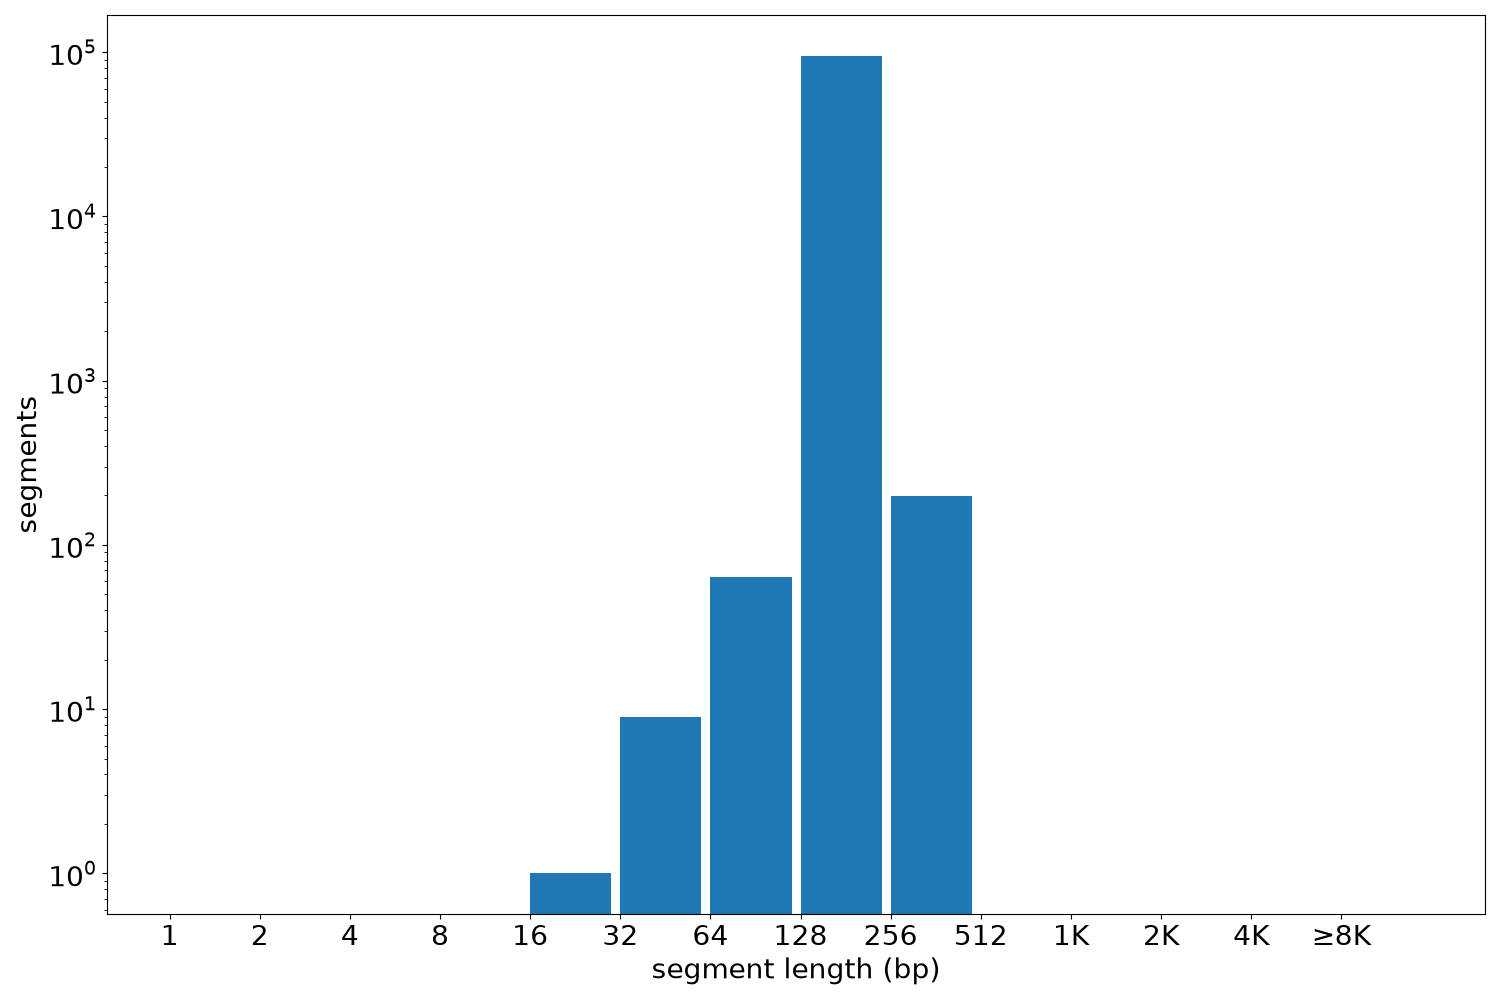
Segment lengths
| segments | min | max | mean | median | |
|---|---|---|---|---|---|
| segments | 95287 | 18 | 450 | 150.28 | 150 |
Files
| Filename | Size | md5 |
|---|---|---|
| ENCFF888QGO.bed.gz | 921.29 KB | cf1f3cdc430833c338cd6a3fc8ba37da |
| ENCFF888QGO.tabix.bed.gz | 791.84 KB | d81b73a39bf8835f8d1fed2615f27010 |
| ENCFF888QGO.tabix.bed.gz.tbi | 388.67 KB | 4b55ff9c010778af9f16976d96956c27 |
| genomic_resource.yaml | 2.71 KB | 1645b8ee6f8af31ddab77bc924936a4d |
| statistics/ |